iFeeling Daily
Daily curated AI insights you can't miss.
Turla’s STOCKSTAY Backdoor: A New .NET Spy Tool Targeting Ukraine and Europe

Google Threat Intelligence Group's deep analysis of Turla's STOCKSTAY backdoor reveals a multi-component .NET implant that's been actively developed since 2022, targeting Ukrainian military and European diplomatic entities. The report includes code overlaps with the KAZUAR toolkit, YARA rules, and detailed operational timelines that are invaluable for threat hunters tracking Russian cyber espionage.
Databricks’ Agent Cloud: Why Open Source and LTAP Matter for AI
Databricks co-founders Matei Zaharia and Reynold Xin unpack Omnigent (an open-source meta-harness above coding and enterprise agents), LTAP (their database bet for live transactional data in column-oriented formats), and why agent security, spend controls, and a common API matter more than ever. The thesis: traditional software gets rewritten once the data is in the right place and agents sit on top.
OpenAI and Broadcom unveil LLM-optimized inference chip Jalapeño

OpenAI and Broadcom unveiled Jalapeño, a custom LLM inference chip designed from scratch with substantially better performance per watt than current accelerators. Taped out in nine months using OpenAI's own models to accelerate chip design, it will deploy at gigawatt scale starting in 2026 as part of a multi-generation platform.
Zero-Day Exploit in Cisco SD-WAN Manager: Attack Chain and Defenses

Mandiant details how a threat actor exploited CVE-2026-20245 in Cisco Catalyst SD-WAN Manager, using rogue peering and credential manipulation to escalate privileges to root and then cover tracks with anti-forensic techniques. The attack chain and detection guidance are essential for any organization running SD-WAN.
NVIDIA NeMo AutoModel: 3.7x Faster MoE Fine-Tuning with One Import Change

NVIDIA NeMo AutoModel delivers 3.4-3.7x higher training throughput and 29-32% less GPU memory for MoE fine-tuning through a single import line change. By adding Expert Parallelism as a dedicated dimension, DeepEP fused dispatch, and TransformerEngine kernels on top of Transformers v5, it makes 550B-scale full fine-tuning feasible and produces standard HF checkpoints for downstream deployment.
How GPT-5 solved an immunologist’s 3-year T cell mystery
Immunologist Derya Unutmaz used GPT-5 Pro to solve a three-year-old puzzle about glucose and T cells, discovering that the model identified a mechanism—IL-2 protein disruption—that his lab had missed. It then correctly predicted results from an unpublished experiment, convincing him these models truly understand biology.
Local Model Triage for OpenClaw: Real-Time, Cost-Free PR Classification
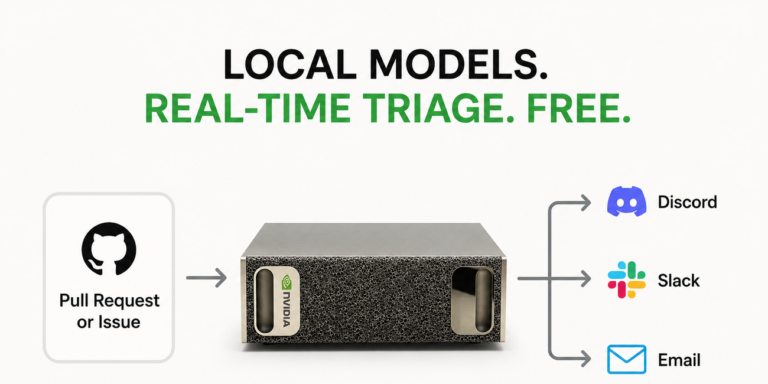
If you own a powerful local machine like the NVIDIA GB10, using models like gemma-4-26b-a4b or qwen3.6-35b-a3b in an agent harness can give you real-time, cost-free triage of open-source contributions. The article provides concrete numbers on precision, recall, and throughput tradeoffs, plus a practical hybrid architecture that uses a cheap cloud audit loop ($9/month) to catch misses.
Shipping weekly releases with AI, open tools, and a human in the loop
Hugging Face cut their release effort from half a day to 15 minutes by using an open-weight AI to draft changelogs, wrapped in deterministic checks that verify every PR is included, and a human review before shipping. The full pipeline is open-source and costs about $0.25 per run.
AI Security After Codex and Claude Code: New Vulnerabilities and Guardrails
This episode from Gray Swan's cofounders explains why AI agents create a new class of security vulnerabilities that traditional cybersecurity cannot solve. Essential for engineers deploying Codex, Claude Code, or similar agents — prompt injection, automated red-teaming, and the lethal trifecta are must-understand concepts.