iFeeling Daily
Daily curated AI insights you can't miss.
Ai2 Finds LLM Novelty Judges Are Unstable on AI-Generated Research Ideas
Small prompt changes swing LLM novelty-judge accuracy by over 50 points on Ai2's new benchmark. Simple baselines beat purpose-built evaluators.
Benchmark’s Full Partnership Takes the Main Stage at Disrupt 2026
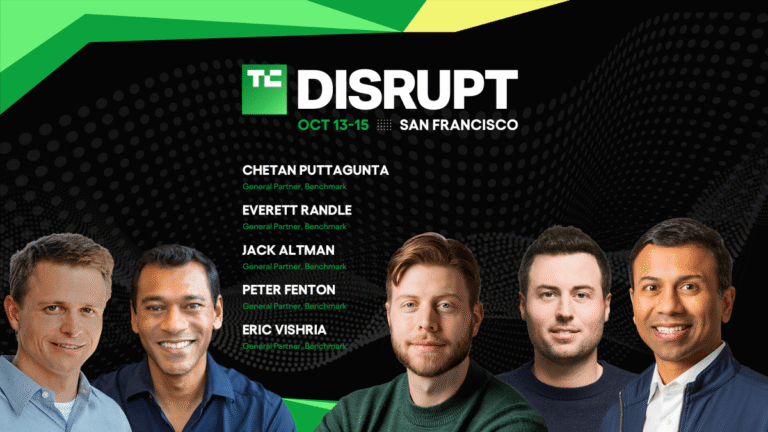
At Disrupt 2026, all five Benchmark general partners will share what they believe now about startup opportunities, AI investing, and where conviction belongs.
Inside GeneBench-Pro: A Genomics Benchmark for Real-World AI Reasoning
GeneBench-Pro is a benchmark that exposes how current AI models struggle with the multi-step, confounding-aware reasoning needed for real genomics tasks like somatic oncology decisions or single-cell eQTL analysis. Each case study provides full datasets and requires models to correct technical artifacts before drawing conclusions.
Using AI to Reanalyze Unsolved Rare Disease Cases and Find New Diagnoses
Researchers used OpenAI o3 Deep Research to reanalyze 376 unsolved rare-disease cases, yielding new diagnoses in 4.8% after experts confirmed findings—demonstrating how AI-assisted periodic reanalysis can uncover answers buried in fragmented genomic data and evolving scientific knowledge.