iFeeling Daily
Daily curated AI insights you can't miss.
Experimenting with GKE Multi-cluster Inference Gateway and TPU Failover
A hands-on walkthrough of deploying Gemma 3 across two GKE clusters with TPU v6e chips, using managed DRANET for accelerator networking and a multi-cluster Inference Gateway for cross-region failover. Covers the full stack from VPC setup to failover verification in production-similar conditions.
Holo3.1: Fast & Local Computer Use Agents
Holo3.1 is a pragmatic upgrade that tackles the real-world challenges of deploying computer-use agents: environment robustness, framework integration, and local inference. With quantized checkpoints and smaller models, it brings state-of-the-art performance to private, on-device execution. If you're building agents that need to work across desktop, mobile, and multiple harnesses, this is worth a close look.
AlloyDB Remote MCP Server GA: Secure AI Agent Access to Your Data
The Remote MCP Server for AlloyDB solves a practical production problem: giving AI agents secure, governed access to real-time operational data without forcing teams to manage their own infrastructure or share database credentials. It turns AlloyDB into a first-class data source for agentic applications, complete with IAM authorization, audit logging, and Model Armor protection.
How Trustpilot built real-time data enrichment with fine-tuned Gemma
Trustpilot built a real-time streaming pipeline for review intelligence by fine-tuning Gemma-2-9b models, achieving frontier-model quality on fixed-cost infrastructure. Their approach decouples business logic from LLM inference and uses teacher model consensus for training data, but teams should plan for GPU scarcity and private networking headaches.
Beyond LLMs: Why Enterprise AI Needs Agent Logic, Not Bigger Models
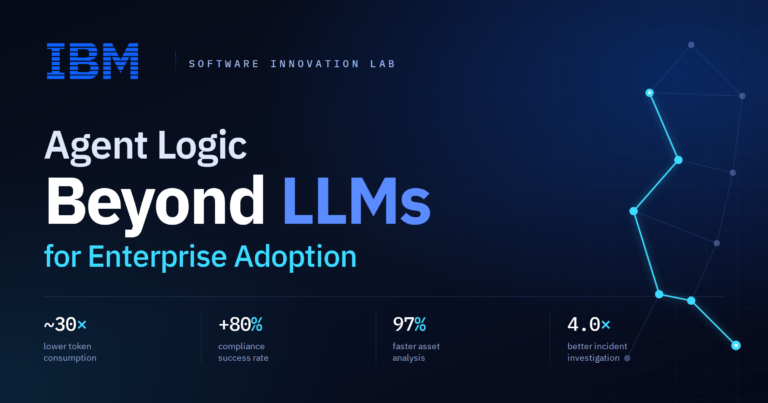
The core tension this article exposes is that powerful frontier LLMs alone are insufficient for enterprise AI adoption, because real enterprise workflows are dynamic, long-running, and tangled with hundreds of APIs, databases, and regulatory constraints. Simply expanding model context to handle these workflows creates a direct tradeoff: increased hallucinations and skyrocketing token consumption. The article argues that the missing piece is not a bigger model but an explicit **agent logic** layer -- software primitives like knowledge graphs, program analysis libraries, and algorithms that operate between the LLM and the workflow to intentionally reduce the context space and steer the model toward policy-compliant, cost-effective outcomes. Without this, AI agents fail to operate at the core of enterprise workflows and AI pilots continue to fail at scale.
The concrete technical path demonstrated across multiple IBM solutions is to equip agents with domain-specific, structured knowledge and orchestration that offloads reasoning from the LLM. For legacy code understanding, **IBM watsonx Code Assistant for Z** uses pre-indexed static analysis to achieve ~30× lower token consumption than a frontier LLM-only approach. For test generation, the Aster library applies program analysis outputs and sub-agents for error remediation, yielding 20-45% coverage improvements with up to 15× fewer tokens. For incident response, the Instana I3 agent uses a knowledge graph of the full IT stack to achieve up to 4× improvement over a ReAct agent with GPT-5.1 while consuming fewer tokens. For compliance, a multi-agent system with adaptive planning boosts success rates from single digits to over 80% with Claude 4 Sonnet. All examples share the same operational insight: bind the LLM with structured guides, not more context.
The takeaway for builders is that scalable enterprise AI deployment requires **investing in agent infrastructure as rigorously as in model selection**. The article makes a convincing case that the bottleneck is not model capability but the absence of an intelligent orchestration layer that can constrain, focus, and validate model outputs against real business policies and data. For any team deploying agents in regulated or complex environments, the practical path forward is to build or adopt agent harnesses that incorporate program analysis, knowledge graphs, and policy-as-code enforcement -- treating the LLM as a flexible reasoning engine rather than a standalone solution. The most performant and cost-effective agents are not the ones with the largest context windows, but the ones with the most tightly scoped, workflow-aware logic.
NVIDIA Cosmos 3: Open Omni-Model for Physical AI Reasoning and Action
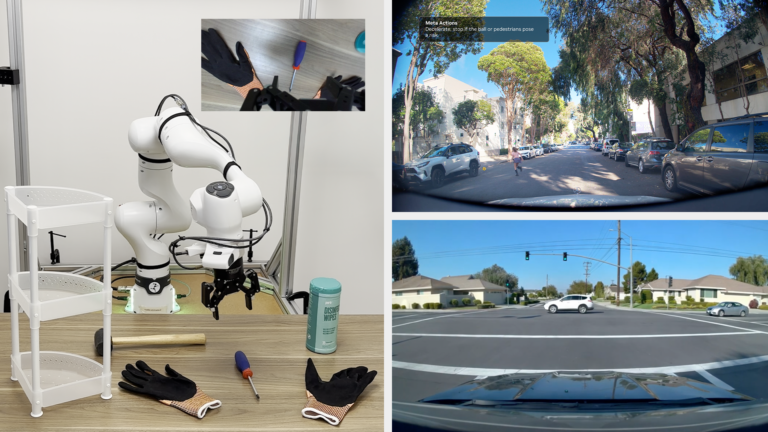
NVIDIA's Cosmos 3 unifies world generation, physical reasoning, and action generation into a single open omni-model, eliminating the need to juggle separate models for robotics, autonomous vehicles, and smart space simulations.
Guide to Gemini Enterprise and A2UI integration
A2UI is an open protocol for agent-driven UI that lets agents emit safe JSON payloads instead of text or HTML. Integrated with Gemini Enterprise, it lets you build agents that render native date pickers, maps, and choice lists inside the GE chat surface—without writing frontend code.
How Google SRE is using agentic AI to improve operations
Google SRE is deploying agentic AI across the entire software lifecycle—from reliability design to incident management—using Gemini and a transparent governance model to handle growing system complexity without sacrificing control. The approach emphasizes explainability, strong agent identity, and backup plans over black-box automation.
Google’s Dataflow innovations for large-scale AI pipelines
Google describes how its internal Flume platform, which powers Gemini and Waymo, feeds into Dataflow for customers like Spotify, Etsy, and Moloco. Key innovations include liquid sharding for straggler mitigation, heterogeneous worker pools for TPU/CPU co-scheduling, and duty-cycle enforcement that scales down idle TPU workers.