iFeeling Daily
Daily curated AI insights you can't miss.
Choosing Your Antigravity Surface: Desktop, CLI, IDE, or SDK
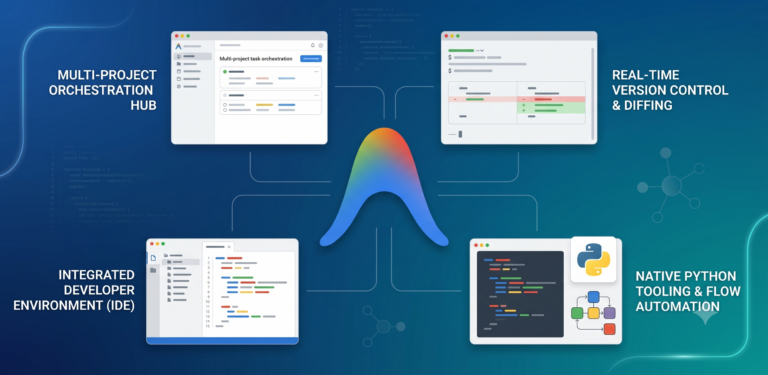
If you're building or choosing an agent platform, the article shows how Antigravity splits into four distinct surfaces—desktop, CLI, IDE, and SDK—all backed by the same shared harness. The key insight is that matching the interface to how you actually work matters more than a one-size-fits-all product.
Holo3.1: Fast & Local Computer Use Agents
Holo3.1 is a pragmatic upgrade that tackles the real-world challenges of deploying computer-use agents: environment robustness, framework integration, and local inference. With quantized checkpoints and smaller models, it brings state-of-the-art performance to private, on-device execution. If you're building agents that need to work across desktop, mobile, and multiple harnesses, this is worth a close look.
AlloyDB Remote MCP Server GA: Secure AI Agent Access to Your Data
The Remote MCP Server for AlloyDB solves a practical production problem: giving AI agents secure, governed access to real-time operational data without forcing teams to manage their own infrastructure or share database credentials. It turns AlloyDB into a first-class data source for agentic applications, complete with IAM authorization, audit logging, and Model Armor protection.
Beyond LLMs: Why Enterprise AI Needs Agent Logic, Not Bigger Models
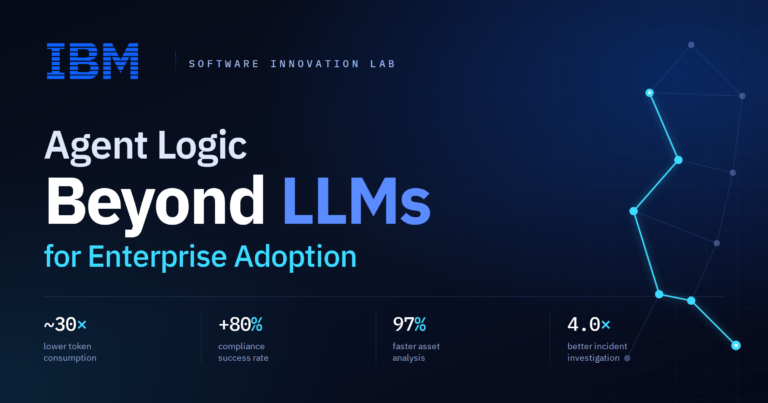
The core tension this article exposes is that powerful frontier LLMs alone are insufficient for enterprise AI adoption, because real enterprise workflows are dynamic, long-running, and tangled with hundreds of APIs, databases, and regulatory constraints. Simply expanding model context to handle these workflows creates a direct tradeoff: increased hallucinations and skyrocketing token consumption. The article argues that the missing piece is not a bigger model but an explicit **agent logic** layer -- software primitives like knowledge graphs, program analysis libraries, and algorithms that operate between the LLM and the workflow to intentionally reduce the context space and steer the model toward policy-compliant, cost-effective outcomes. Without this, AI agents fail to operate at the core of enterprise workflows and AI pilots continue to fail at scale.
The concrete technical path demonstrated across multiple IBM solutions is to equip agents with domain-specific, structured knowledge and orchestration that offloads reasoning from the LLM. For legacy code understanding, **IBM watsonx Code Assistant for Z** uses pre-indexed static analysis to achieve ~30× lower token consumption than a frontier LLM-only approach. For test generation, the Aster library applies program analysis outputs and sub-agents for error remediation, yielding 20-45% coverage improvements with up to 15× fewer tokens. For incident response, the Instana I3 agent uses a knowledge graph of the full IT stack to achieve up to 4× improvement over a ReAct agent with GPT-5.1 while consuming fewer tokens. For compliance, a multi-agent system with adaptive planning boosts success rates from single digits to over 80% with Claude 4 Sonnet. All examples share the same operational insight: bind the LLM with structured guides, not more context.
The takeaway for builders is that scalable enterprise AI deployment requires **investing in agent infrastructure as rigorously as in model selection**. The article makes a convincing case that the bottleneck is not model capability but the absence of an intelligent orchestration layer that can constrain, focus, and validate model outputs against real business policies and data. For any team deploying agents in regulated or complex environments, the practical path forward is to build or adopt agent harnesses that incorporate program analysis, knowledge graphs, and policy-as-code enforcement -- treating the LLM as a flexible reasoning engine rather than a standalone solution. The most performant and cost-effective agents are not the ones with the largest context windows, but the ones with the most tightly scoped, workflow-aware logic.
Guide to Gemini Enterprise and A2UI integration
A2UI is an open protocol for agent-driven UI that lets agents emit safe JSON payloads instead of text or HTML. Integrated with Gemini Enterprise, it lets you build agents that render native date pickers, maps, and choice lists inside the GE chat surface—without writing frontend code.
Skill Distillation: Teaching Small Models Procedures via Markdown
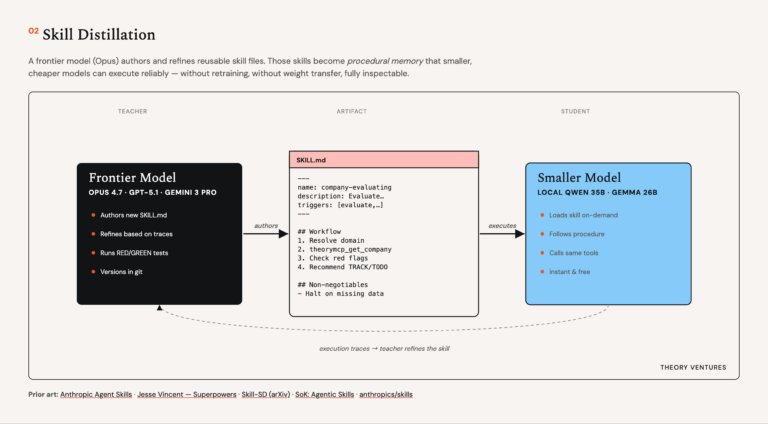
Skill distillation lets a frontier model write procedural markdown files that a small local model executes, separating the expensive reasoning from the reliable execution. This lets you run capable personal agents on your own computer with cheap models that just follow steps.
Google MENA-T Accelerator: 15 AI-First Startups Tackle Geopolitical Risk
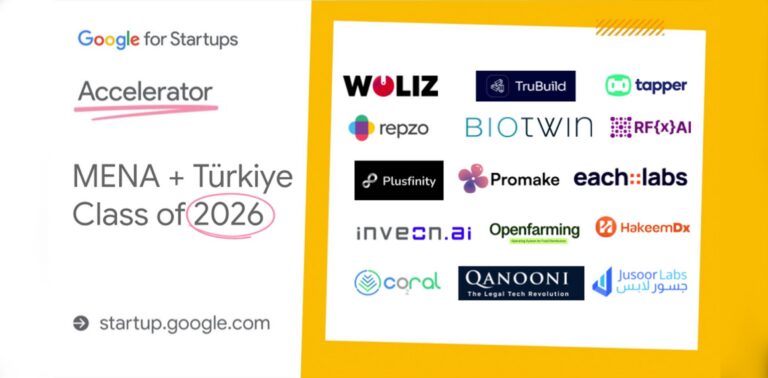
Google’s new MENA-T accelerator cohort pairs deep technical stack audits and AI security training with real cloud infrastructure. With past startups like COGNNA achieving 80% faster analyst workflows and Smart Bricks automating 99% of real estate workflows, the program shows how targeted mentorship and Google Cloud tooling can help founders scale despite geopolitical uncertainty.
ITBench-AA Benchmark: Frontier Models Score Below 50% on Agentic SRE Tasks
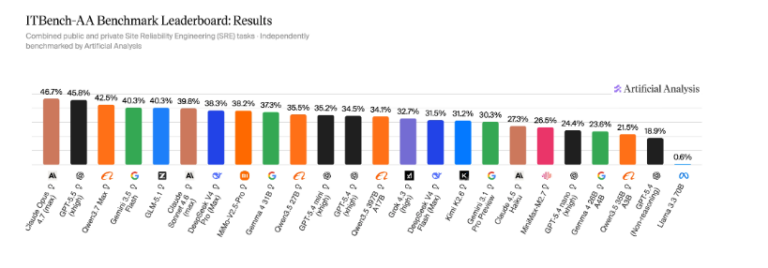
ITBench-AA reveals that frontier models, including Claude Opus 4.7 at 47%, struggle to diagnose Kubernetes incidents with recall-gated precision. Open weights models like Gemma 4 31B at 37% offer cost-effective alternatives, highlighting the need for agentic reasoning that avoids over-investigation.
The Harness Era: Seven Disciplines for Domesticating AI in Production
The software era of fixed-workflow SaaS is over; the harness era is here. If every company has access to the same AI models, the winners will be those who build the best systems for context retrieval, tool orchestration, state persistence, and observability. This is a pragmatic guide for engineers deciding where to invest their infrastructure effort.