iFeeling Daily
Daily curated AI insights you can't miss.
Hardening Google Cloud Access Management with IAM Conditions
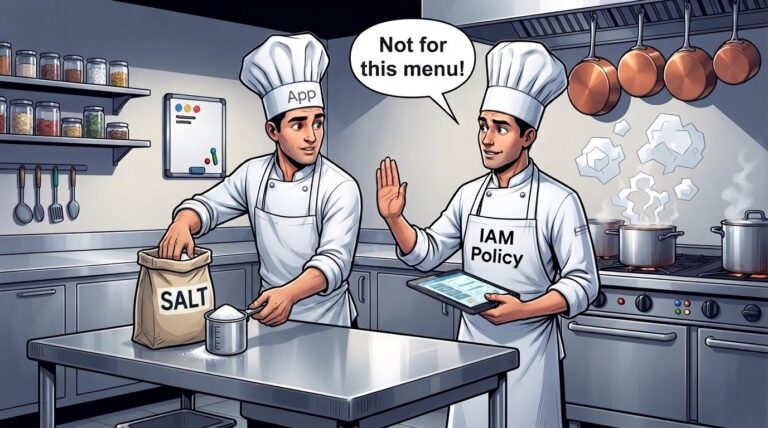
Use IAM conditions in CEL to constrain admin roles and MCP server access beyond standard Allow and Deny policies.
Supercharge pgvector: 4x Faster HNSW with AlloyDB
AlloyDB's columnar engine accelerates HNSW vector search up to 4x faster QPS than standard PostgreSQL, enabling higher recall and lower costs.
CodeMender in Preview: AI-Powered Code Security Agent
CodeMender scans, verifies, and remediates code vulnerabilities autonomously, using Gemini and Wiz to reduce manual bottlenecks in security workflows.
Gritt exits stealth with $34M for AI-driven solar construction robots
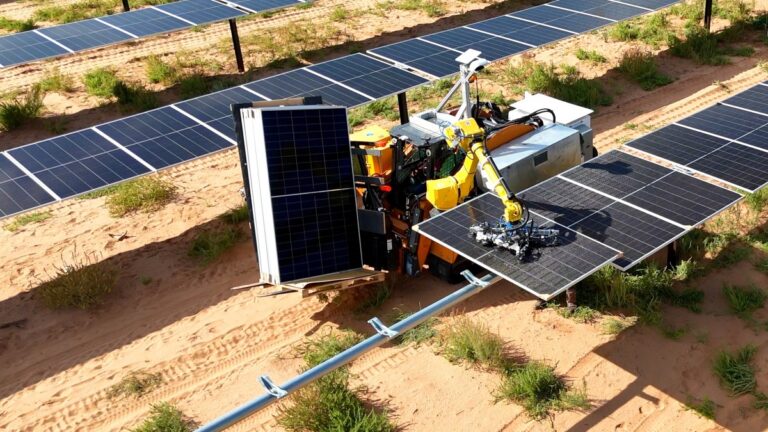
Gritt exits stealth with $34M to deploy off-the-shelf robots controlled by AI for solar panel installation, targeting 2.8 GW in 18 months.
Grabette: Open System for Recording Robot Manipulation Data by Hand
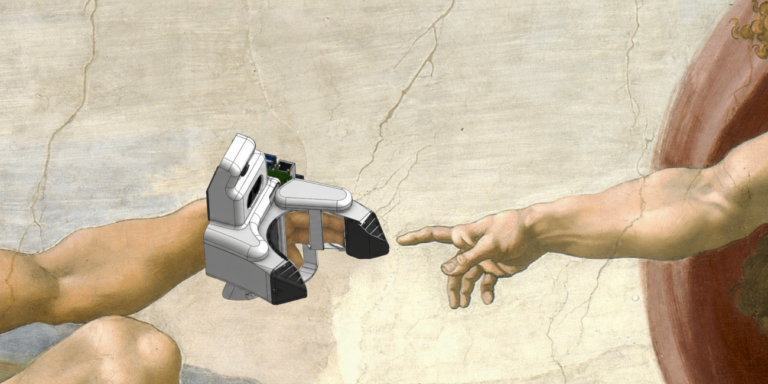
Grabette is an open, low-cost handheld system for recording robot manipulation data by hand, turning demonstrations into standard LeRobot datasets without requiring a robot.
Google 研发高效 AI 芯片 Frozen v2,计划 2028 年让 Gemini 效率提升 6-10 倍
Google 正在秘密研发代号 Frozen v2 的新一代 AI 推理芯片,目标 2028 年发布,效率相比现有方案提升 6 到 10 倍。这对于关注 AI 基础设施成本和摆脱 Nvidia 依赖的工程师来说,是需要提前关注的关键动向。
AI’s most important protocol is getting a little bit easier to use
The Model Context Protocol is switching to a stateless session ID model, eliminating the need for servers to share state across load balancers. This simplifies scaling MCP deployments, removing a major roadblock to large-scale AI agent integrations that rely on accessing external data.
BigQuery Search innovations: Unify structured & unstructured data
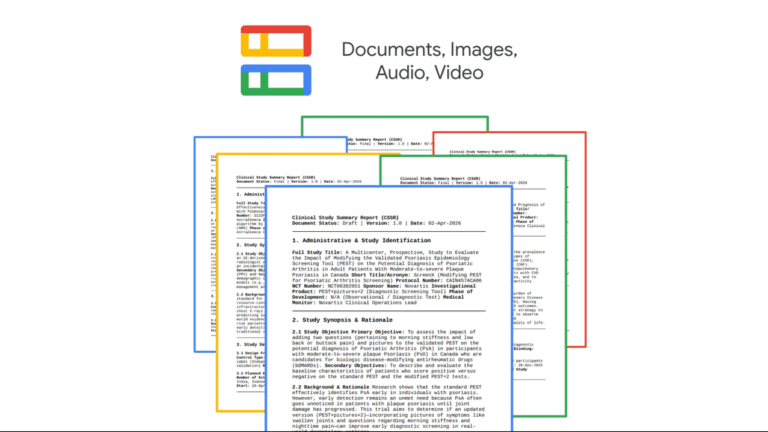
BigQuery now offers Autonomous Embedding Generation, AI.SEARCH with 133x slot efficiency gains, and Hybrid Search—all inside SQL. This turns unstructured data (PDFs, images, audio) into a first-class citizen, replacing fragmented pipelines with a single warehouse platform for grounding, retrieval, and conversational analytics.
LVSum Benchmark Tests Multimodal Models on Temporal Video Summarization
LVSum is a new benchmark exposing how even advanced multimodal models fail at temporally grounded video summarization. With 72 long videos and human-written summaries containing precise time references, it reveals that transcripts matter far more than visuals and that current MLLMs systematically lack temporal awareness.