iFeeling Daily
Daily curated AI insights you can't miss.
A Guide to AI Cold Starts on Cloud Run
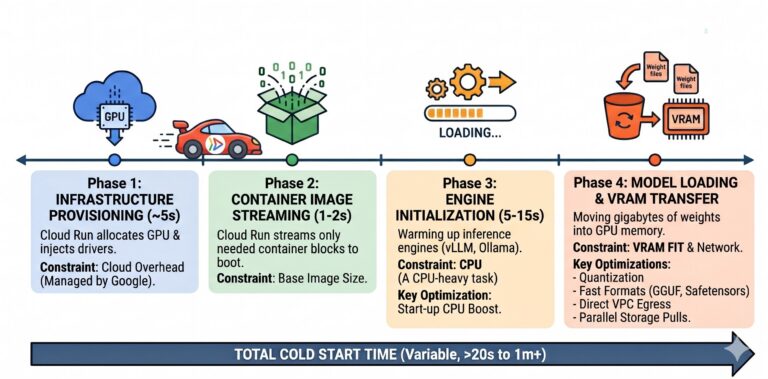
This article dives deep into the mechanics of AI cold starts on Cloud Run, breaking down the four phases and providing concrete strategies to reduce latency from 20 seconds to manageable levels, including quantization, startup CPU boost, and concurrency tuning from Google's formula.
(1D) Ordered Tokens Enable Efficient Test-Time Search

Researchers show that using 1D ordered tokenizers with a coarse-to-fine structure in autoregressive image generation significantly improves test-time search efficiency, enabling better scaling behavior and even training-free text-to-image generation when guided by an image-text verifier.
Nemotron-Labs Diffusion: Fast Text Generation via Self-Speculation
Nemotron-Labs Diffusion lets developers pick AR, diffusion, or self-speculation inference from one checkpoint—self-speculation delivers up to 6.4× tokens-per-forward-pass gain over pure AR with lossless accuracy. Practical, open, and ready to test through SGLang.
Amortizing Maximum Inner Product Search with Learned Support Functions

This paper proposes amortized MIPS, using SupportNet and KeyNet neural networks to directly predict maximum inner product search solutions, significantly improving IVF match rates on the BEIR benchmark while reducing computational cost.
OpenAI’s Research Chief on Scaling Laws, o1, and the Evals Crisis

Mark Chen, OpenAI's Chief Research Officer, discusses scaling laws, the reasoning bet behind o1, the evals crisis, and how OpenAI allocates compute to pursue AGI. The conversation covers developing research taste, long-context learning, and why pre-training remains critical for frontier progress.
Most AI Work Can Wait

Most AI teams pick the model first, then architecture. That's backward. The router—not the model—determines cost and performance; 70-80% of traffic can run on free local models.
FFASR Leaderboard: Open Benchmark for Far-Field ASR

The FFASR Leaderboard reveals far-field WER at low SNR is consistently several times higher than near-field WER on the same speech content across all models.
Beyond LoRA: Systematic PEFT Benchmarks Show Other Techniques Can Beat It

LoRA dominates PEFT usage but systematic benchmarks show other techniques like OFT can strictly outperform it on image generation, and variants like rs-LoRA matter for LLMs.
Atlas Scales Hundreds of Cloud SQL Databases with Enterprise Plus

Atlas migrated hundreds of isolated Cloud SQL databases to Enterprise Plus, reducing database ops time by 30% and enabling proactive performance management.