Block Removal as an Ising Optimization Problem for LLM Deep Pruning
The article describes a new method for LLM depth pruning—removing entire transformer blocks—reformulated as a constrained binary optimization (CBO) problem that maps directly onto an Ising glass. The authors are from Multiverse Computing, and the work is presented in the paper LLM Compression by Block Removal with Constrained Binary Optimization, with code open-sourced at github.com/CompactifAI/Block_removal_through_constrained_binary_optimization.
Block removal is attractive because it makes the model physically shorter, producing predictable inference speedups on top of memory savings, and it composes with quantization, low-rank compression, and other techniques. The hard part is selecting which blocks to delete, because the effect of removing one block depends on which other blocks are removed alongside it. The authors argue that this makes the problem combinatorial, not a ranking problem, and that interacting binary variables are exactly what spin-system physics describes.
Most existing methods score each block independently using magnitude, sensitivity, or block-influence heuristics. The authors call these mean-field methods because they treat each block as if its contribution were independent of the others. A common shortcut is to remove only a single consecutive run of blocks, which shrinks the search space but discards most configurations. The problem is that blocks are coupled: whether removing block 20 hurts depends on whether you also removed block 19 or block 24. As models get deeper and more heterogeneous, ignoring these couplings leaves quality on the table, especially at aggressive compression levels.
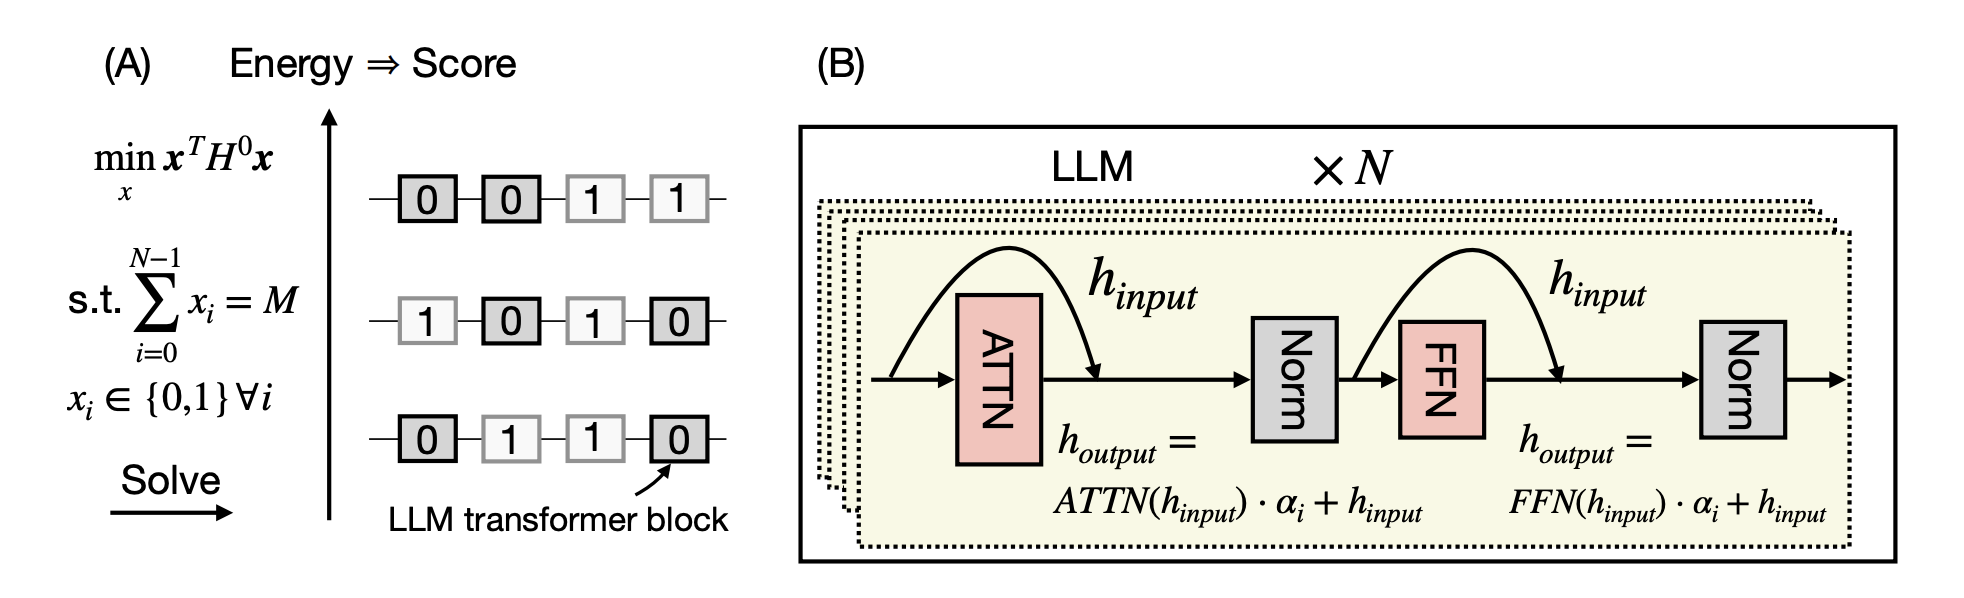
The proposed approach attaches a binary variable to each transformer block: 0 means keep, 1 means remove. A second-order Taylor expansion of the model’s loss with respect to these variables produces an approximate Hessian matrix. The diagonal captures each block’s individual importance; the off-diagonal entries are the pairwise couplings between blocks. The optimization is then to find the set of M blocks whose removal minimizes x^T H^0 x, subject to removing exactly M of N blocks. Mathematically this is constrained binary optimization; physically it is an Ising glass with all-to-all couplings and conserved magnetization, where the fixed number of removed blocks plays the role of fixed total spin. The key property established in the paper is that this energy is a strong proxy for downstream quality: low-energy states correspond to high-performing pruned models.
The practical benefit is cost. The Hessian is computed once from forward and backward passes on a small calibration dataset. After that, evaluating a candidate configuration is a single cheap energy calculation, with no need to run the model or benchmark it. The couplings do not depend on the compression target, so the same Hessian can be reused for many values of M. For tractable cases the authors brute-force the search on a single GPU, checking up to tens of billions of spin configurations. The hardest tractable case, removing 8 of Llama-3.3-70B’s 80 blocks (about 29 billion configurations), took roughly two days. For harder cases, the QUBO form with the constraint absorbed into a penalty term can be handed to classical, quantum, and quantum-inspired solvers: quantum annealing, QAOA, tabu search, and branch-and-bound. An open-source tabu solver reliably reaches the lowest-energy states in seconds, even on the hardest cases they can verify against brute force.
A subtle point is that the ground state is not required. The energy is a strong proxy but not perfect, so the lowest-energy state is not always the best model. The authors instead want a fast way to generate several good low-energy states, which is an easier bar and explains why lightweight solvers work well. Once the Hamiltonian is set up, reading off the ground state and low-lying excited states is essentially free, giving a spectrum of candidate prunings. For Llama-3.1-8B-Instruct at 16/32 blocks removed, most top states cut blocks toward the end of the model, but the 17th excited state is the first to propose removing a block near the beginning; after light retraining, that configuration outperforms the ground state on several benchmarks. This directly disproves the assumption that the best pruning is one consecutive chunk of middle-or-late blocks.
Results are reported across Llama-3.1-8B-Instruct, Qwen3-14B, and Llama-3.3-70B-Instruct. The method is on par with or better than state-of-the-art baselines, with the gap widening as compression increases. The clearest win is deep compression of Llama-3.3-70B-Instruct without retraining: up to 24/80 blocks removed, CBO is roughly on par with block influence, but at 32/80 and 40/80 it pulls ahead, with an almost 23-point MMLU advantage at 40/80 (76.9 vs. 54.0). For Qwen3-14B at 12/40 removed, CBO leads MMLU by about 10 points. At lighter compression the methods are comparable, which is expected because couplings matter most when cutting deep.
The method also transfers to heterogeneous architectures. The authors tested it on NVIDIA-Nemotron-3-Nano-30B-A3B-FP8, a hybrid model interleaving Mamba2, attention, and mixture-of-experts (MoE) layers. Removing 2–3 MoE layers or 2 attention layers, CBO finds configurations that beat block influence on AIME25 and GPQA. The results confirm that redundancy in hybrid models is real but unevenly distributed, and the best configuration is often an excited state rather than the ground state. The authors frame the work as fitting Multiverse Computing‘s broader approach: reformulating a machine-learning problem as an Ising Hamiltonian and solving it with classical and quantum-inspired optimization, composing block removal with quantization, low-rank/SVD compression, width pruning, and knowledge-distillation-based healing.