iFeeling Daily
Daily curated AI insights you can't miss.
PostgreSQL for agents in AlloyDB enters preview
Google Cloud previews PostgreSQL for agents in AlloyDB, adding sandboxed serverless instances with real-time read access to production data.
LFM2.5-VL-DSpark: Speculative Decoding for VLMs
Liquid AI's LFM2.5-VL-DSpark adds a 280M-parameter draft model to LFM2.5-VL-3B, giving decode speedups up to 3.13x on device with minimal memory overhead.
What AI startups want from Google Cloud’s stack
Google Cloud says startups are adopting its stack at a higher rate than three years ago, driven by compute choice, agent-building tools, and AI security products.
Google Cloud Networking for Fluid Compute AI Workloads
Google Cloud networking adapts to accelerator choices for AI workloads, covering resource scheduling, GPU fabrics, TPU interconnects, and Cloud Run egress.
Scaling MuJoCo to 2,048 Parallel GPU Worlds with NVIDIA Warp and MJWarp
MJWarp ports MuJoCo physics to NVIDIA Warp, advancing thousands of independent worlds per step. A gated workflow validates one-world parity before scaling to 2,048 environments.
GKE Adds Native Scale-to-Zero with Capacity Buffers
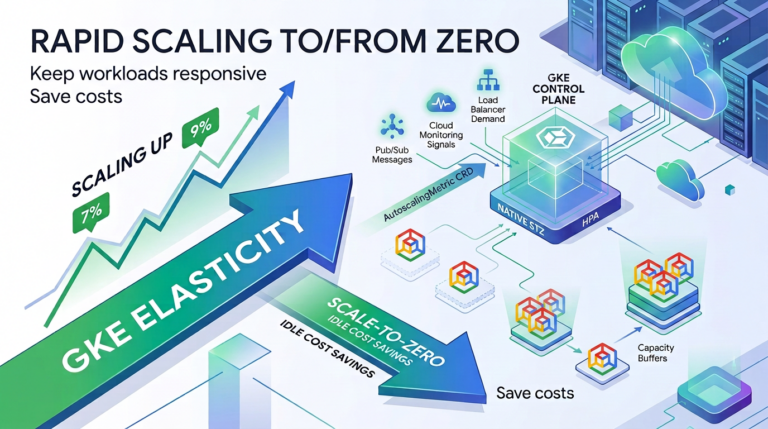
GKE 1.37 adds native scale-to-zero using HPA with AutoscalingMetric and KEP-2021, plus capacity buffers to reduce cold-start latency for event-driven and sporadic workloads.
GKE Natively Supports Prometheus Metrics for Autoscaling
GKE now natively supports Prometheus metrics for autoscaling, enabling PromQL-based HPA triggers directly from Cloud Monitoring without third-party adapters.
Ringg’s AI Agents Resolve Up to 65% of Customer Calls with OpenAI
Ringg's AI agents resolve up to 65% of routine customer calls without human help, handling over 7 million connected calls per month across voice, chat, WhatsApp, and the web.
Parallel Cuts Research Time and Cost in Half with GPT-6 Astra
Parallel reports that GPT-6 Astra completed a research task in half the time and with roughly 50% code cost reduction while maintaining the same quality.