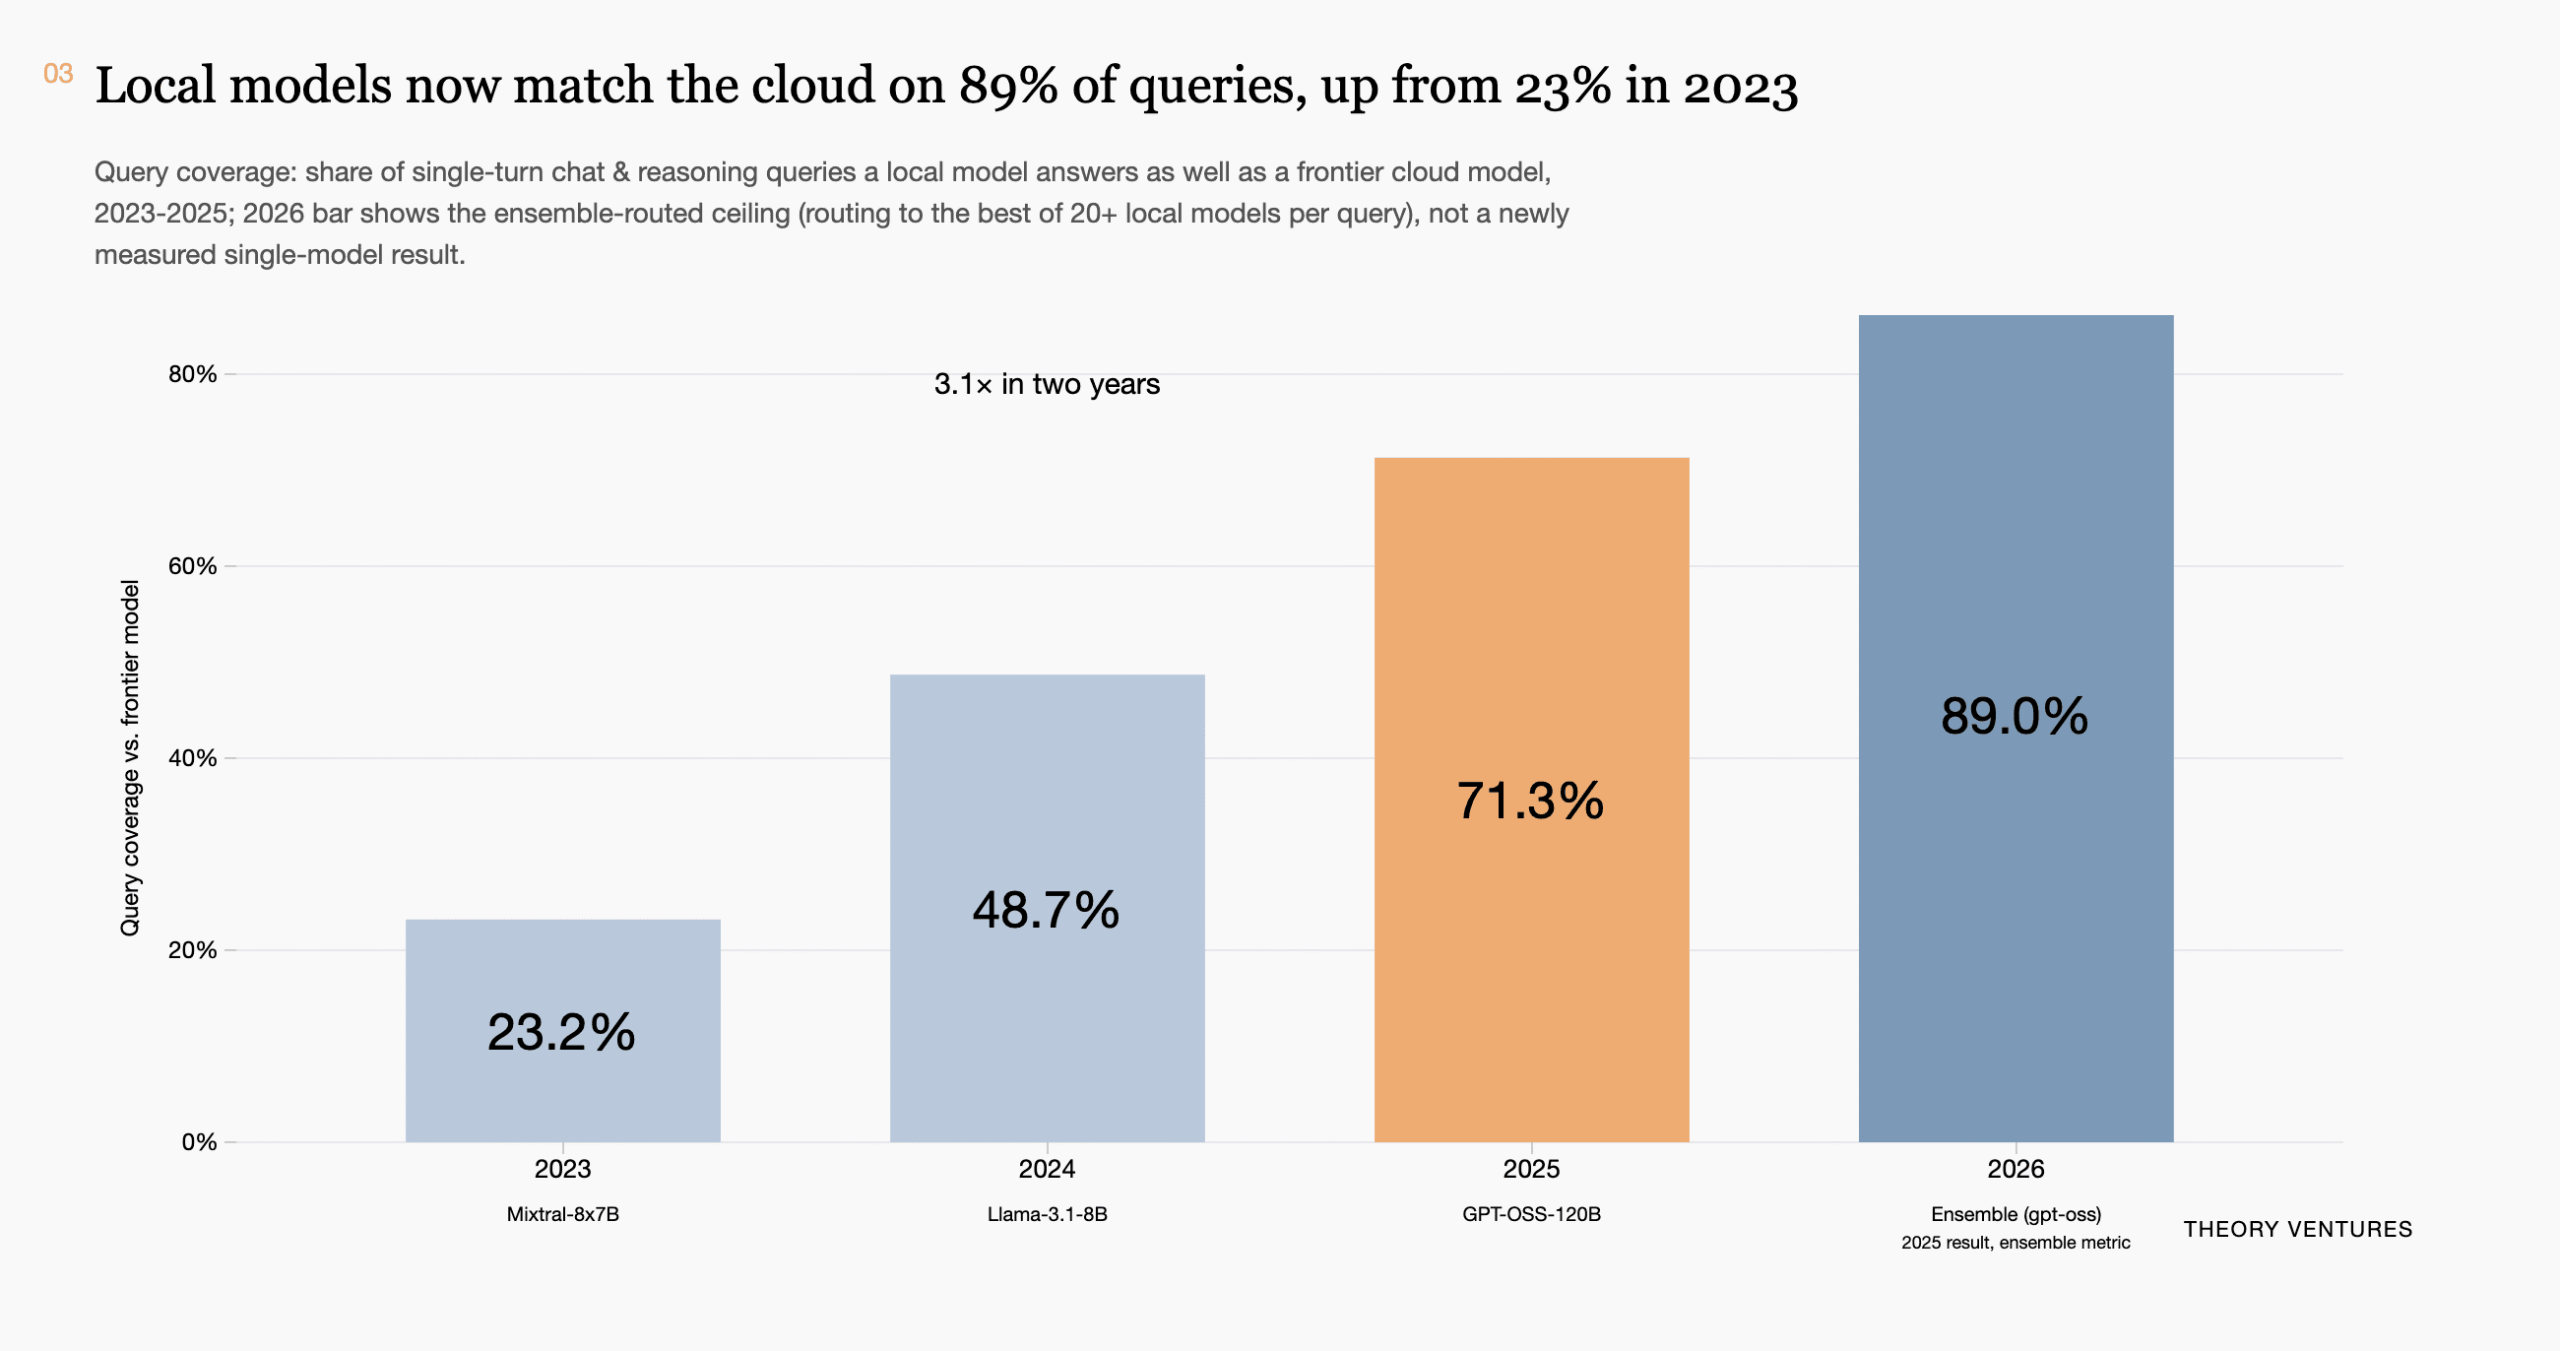
Local AI Models Match Cloud on 89% of Queries: The Edge AI Shift
The article “Mainframes became personal. So will your data center.” argues that local AI models are rapidly approaching the quality of frontier cloud models for everyday queries, making AI inference at the edge increasingly viable and efficient. Citing the paper “Intelligence per Watt,” it reports that local models already match or surpass a frontier cloud model on 89% of over a million real-world chat and reasoning queries, across 20+ local models tested. This shift is framed in terms of “intelligence per watt,” analogous to Koomey’s law, which observed that computing power per watt doubled roughly every 1.5 years for decades, enabling mainframe-class power to shrink into personal computers. The article suggests that similar efficiency gains will drive AI’s transition to edge devices.
However, the article notes that GPU efficiency has been doubling more slowly, roughly every 2.7 years over the past 15 years. Despite this, the win/tie rate of the best local model against a frontier model has climbed from 23.2% in 2023 to 71.3% in 2025, adding about 20 percentage points per year. By 2026, with a local model router, that rate could approach 90%. Simultaneously, intelligence-per-watt improved 5.3x over the same period, with 3.1x coming from better models and 1.7x from better chips. These gains highlight that both algorithmic and hardware improvements are contributing to edge inference feasibility.
The article acknowledges that cloud computing remains essential for long multi-step reasoning, the hardest technical domains, and workloads requiring scale and parallelization. Cloud hardware still holds an edge in many use cases; for instance, cloud inference delivers a 40% energy efficiency gain over local models because datacenters can batch queries, a technique not yet available to single-user local hardware. Nevertheless, for most everyday knowledge work, sending queries to the cloud is unnecessary. Combining local models with a router is sufficient for the supermajority of tasks. This approach cuts energy consumption by 80%, compute by 77%, and cost by 74% compared to an all-cloud baseline. The article concludes that just as mainframes became personal, so will data centers, with local inference becoming the default for many applications.