Liquid AI Releases Open d1-3B and d1-omni-600M Edge Decision Models
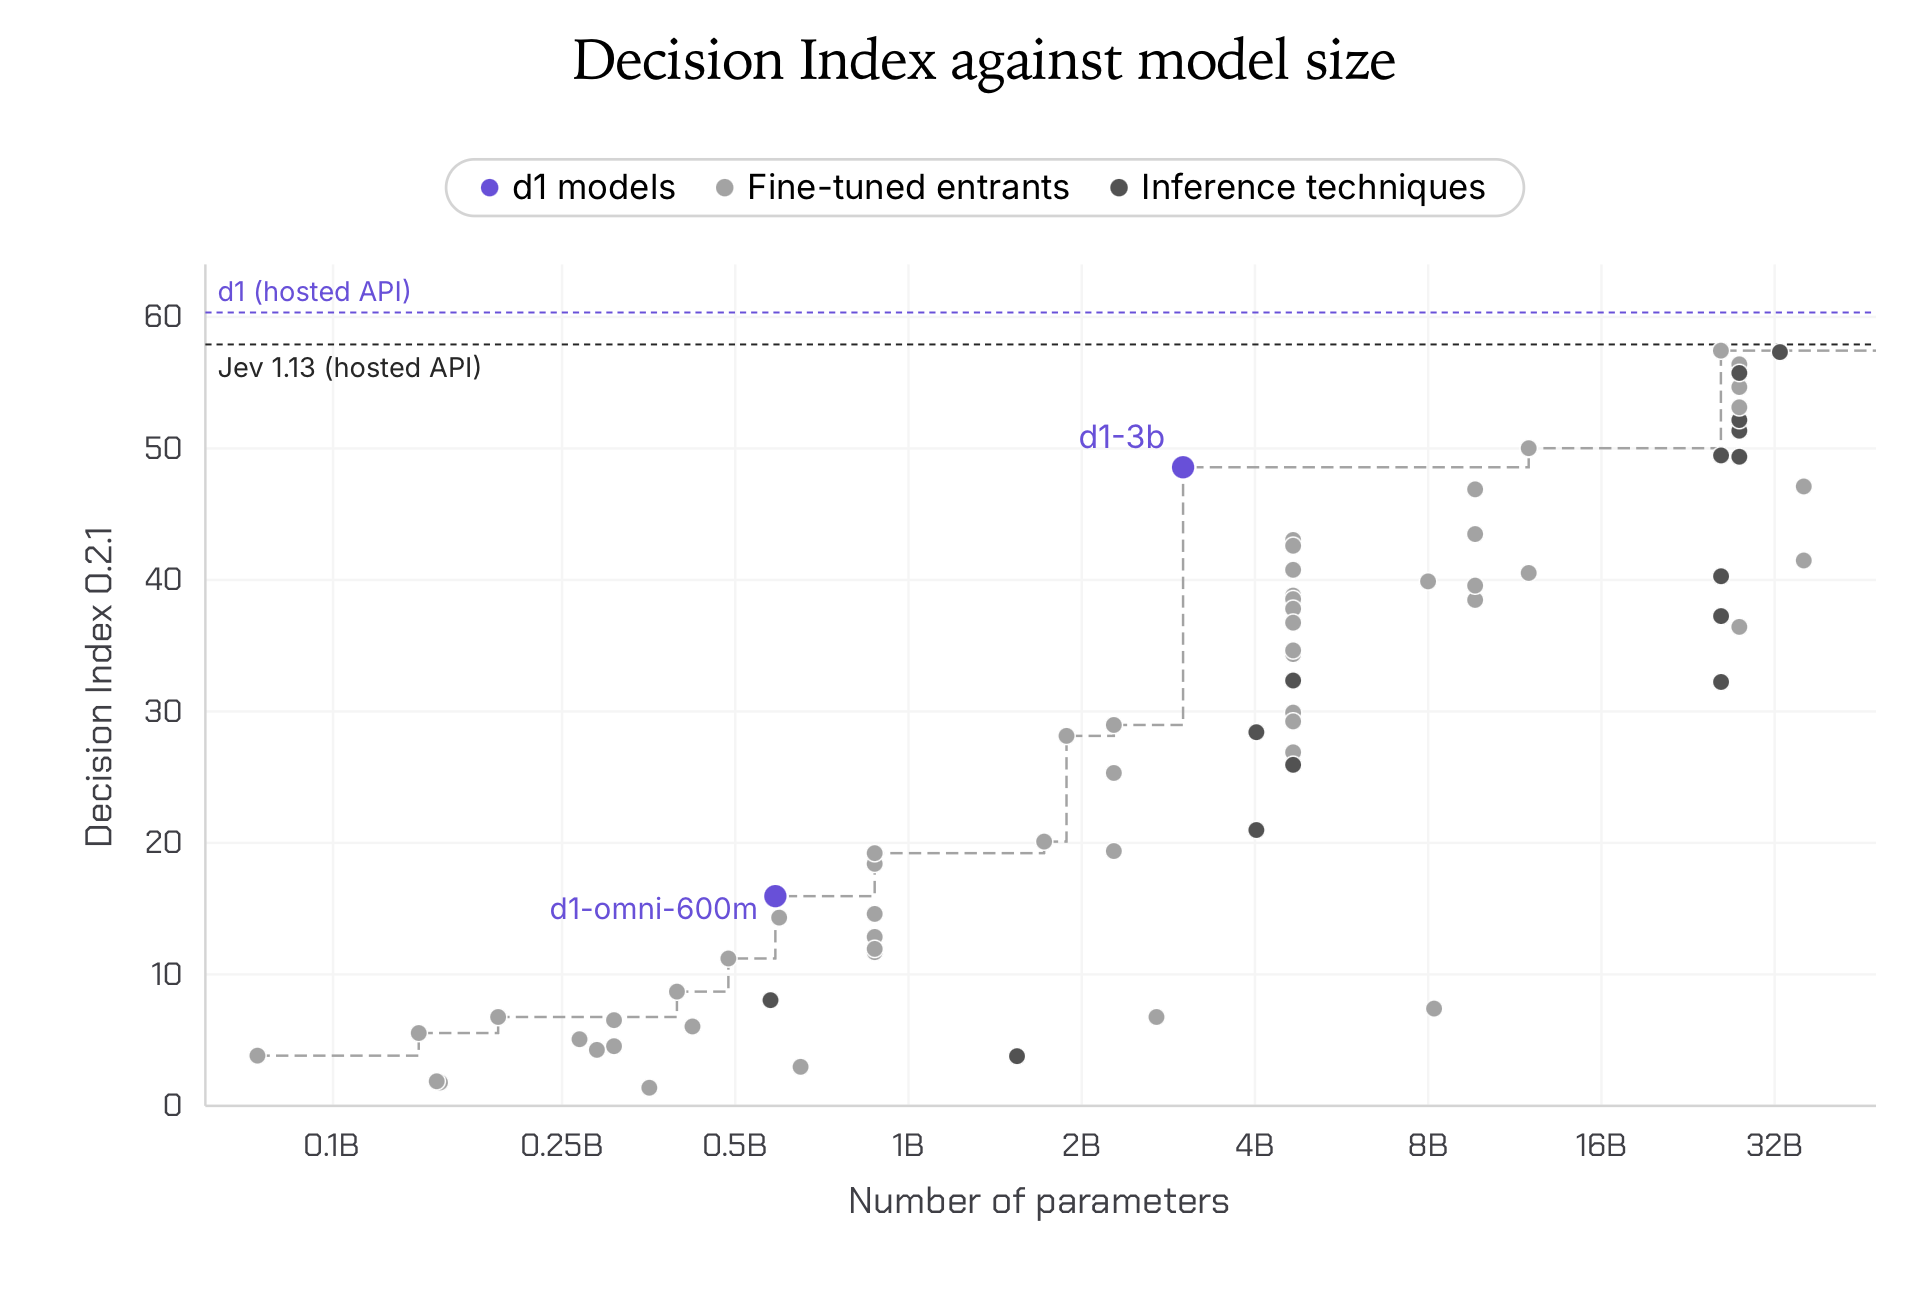
Liquid AI released two open decision models in its d1 family: d1-3B and d1-omni-600M (experimental). Unlike generative models, decision models do not produce tokens; they answer in a single forward pass. On the Decision Index 0.2.1, d1-3B scores 48.57, the best decision model under 10B and ahead of Decider 35B-A3B (47.11). d1-3B accepts text and images, while d1-omni-600M handles text with either images or audio.
The models are built on Liquid Foundation Models but from different backbones: d1-3B is trained from LFM2.5-VL-3B, a decoder-only vision-language model, and d1-omni-600M is trained from LFM2.5-Encoder-350M, a bidirectional encoder with added vision and audio encoders. The 600M model is an early research release still under development.
On seven public datasets covering reading comprehension, toxicity detection, intent classification, medical QA, and cross-lingual understanding, d1-3B reaches a mean score of 82.9, above Decider 4B’s 81.1. d1-omni-600M scores 78.4, surpassing Decider 2B (77.1) with a quarter of the parameters. Notable per-dataset results include d1-3B at 83.3 on SQuAD 2.0 and 93.3 on Civil Comments, while d1-omni-600M leads Civil Comments at 95.8 and achieves 86.1 on MASSIVE intent. The authors validated that d1-3B keeps the vision capabilities of its backbone and that d1-omni-600M handles all three modalities, but they do not report vision or audio benchmarks because Decision Index v0.3 includes only a private vision split and audio decision benchmarks are still an open problem.
In collaboration with NVIDIA, Liquid AI measured d1-3B on GeForce RTX 4090, Jetson AGX Thor, Jetson AGX Orin 64 GB, and Jetson Orin Nano. On edge devices, d1-3B answers a single question in under 50 ms everywhere: 16 ms on AGX Thor, 26 ms on AGX Orin, and 50 ms on Orin Nano. Three questions cost only 1.3x the time of one, with Thor going from 16 ms to 20 ms. A 3.4K-token state takes 220 ms on Thor and 1,640 ms on Orin Nano; packing 64 states reaches 262 decisions per second on Thor and 38 per second on Orin Nano. On GPU, d1-3B answers a question in under 10 ms and processes a 384px image in under 18 ms on both RTX 4090 and AMD MI325X, with packed throughput of 475/s and 1,106/s respectively. No speed numbers are reported for d1-omni-600M because it is an early research release.
The release includes code examples for loading d1-3B with transformers>=5.14 using trust_remote_code=True, then defining named questions with types such as choice, score, and noul. The system_one API can answer several questions over one text state, classify an image passed as the whole state, and system_one_batch processes many requests packed together without padding. The models are open-weight and available on Hugging Face, with demos in the System One Arcade Space. The intended use is fast, structured decisions, including multimodal inputs, where d1-3B offers the highest quality at its size and d1-omni-600M targets small-footprint deployments.