Dharma Field Extractor: Structured JSON from Any Document with a 2B Model
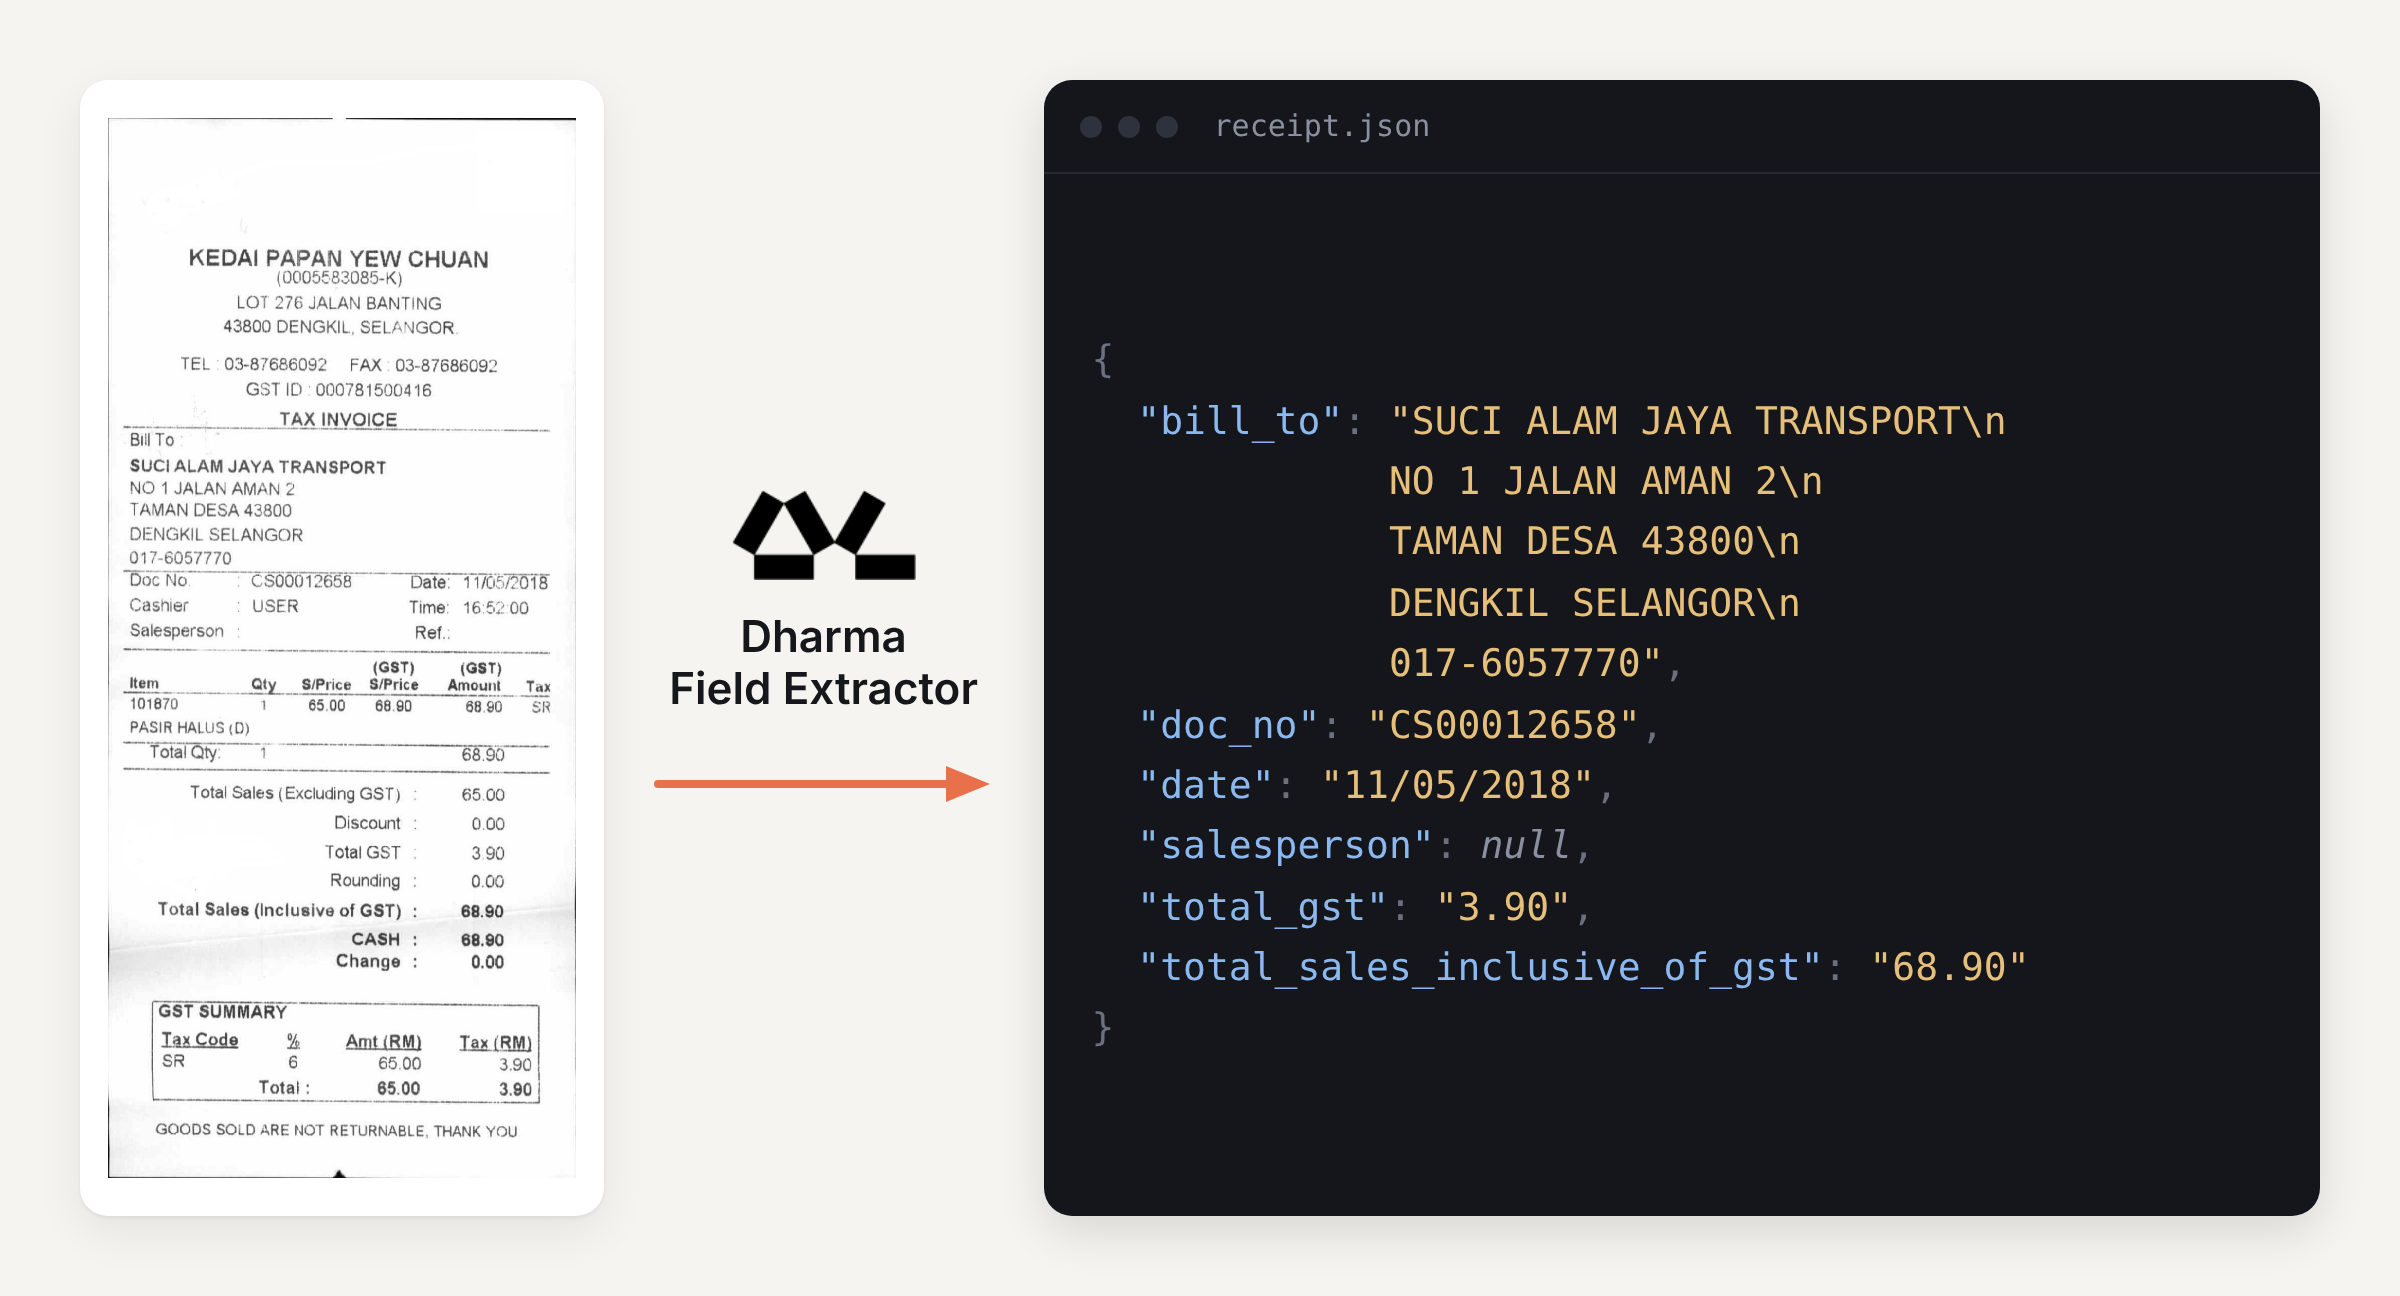
Dharma-AI released the Field Extractor, a 2-billion-parameter model built on DharmaOCR-LITE v1.1 that takes a document image and returns structured JSON. Instead of transcribing the whole page the way OCR does, it pulls out exactly the fields a downstream system needs: invoice line items, patient and exam details from medical requisitions, ID fields mapped to employee-record columns.
The model supports two request modes. In open mode, no schema is supplied and it identifies structured fields from context and layout, returning key-value pairs. In schema-directed mode, the caller specifies the exact keys and types, and the output follows that shape exactly, including null for fields that are not on the document. The same checkpoint handles both modes without per-type fine-tuning.
Training added a LoRA adapter to the DharmaOCR-LITE v1.1 checkpoint on 43,384 field-level annotated examples in three streams: English multi-domain documents from the public web, Brazilian documents in Portuguese, and a smaller multilingual share. The mix spans receipts, invoices, forms, bank statements, ID documents, and synthetic documents.
The benchmark covers 546 documents across three scenarios — no schema, a partial schema with real fields, and a schema with deliberately nonexistent fields — for 1,638 total cases. The score is field-level F1 matched by path, multiplied by Levenshtein similarity on matched values and by the share of valid JSON outputs. The Field Extractor scored 0.834, above Claude Opus 5 at 0.816 and GPT-5.6 Luna at 0.741. Cost comparisons run from roughly 6 times lower than GPT-5.6 Luna to roughly 147 times lower than GPT-5.6 Sol, based on measured tokens per page against provider list pricing and self-hosted GPU time on a single L40S at $2.24 per hour.
The article explicitly says this is not a sales price: self-hosted cost depends on hardware, volume, and latency. On held-out public datasets SROIE and FUNSD, the model recovered all requested fields, including nulls for blank values and one checked boolean among twelve. The authors present this as further evidence for their specialization thesis: on a bounded task, a small model trained close to the task beats a frontier model asked to do the same thing generally, at substantially lower cost.