Ai2 Finds LLM Novelty Judges Are Unstable on AI-Generated Research Ideas
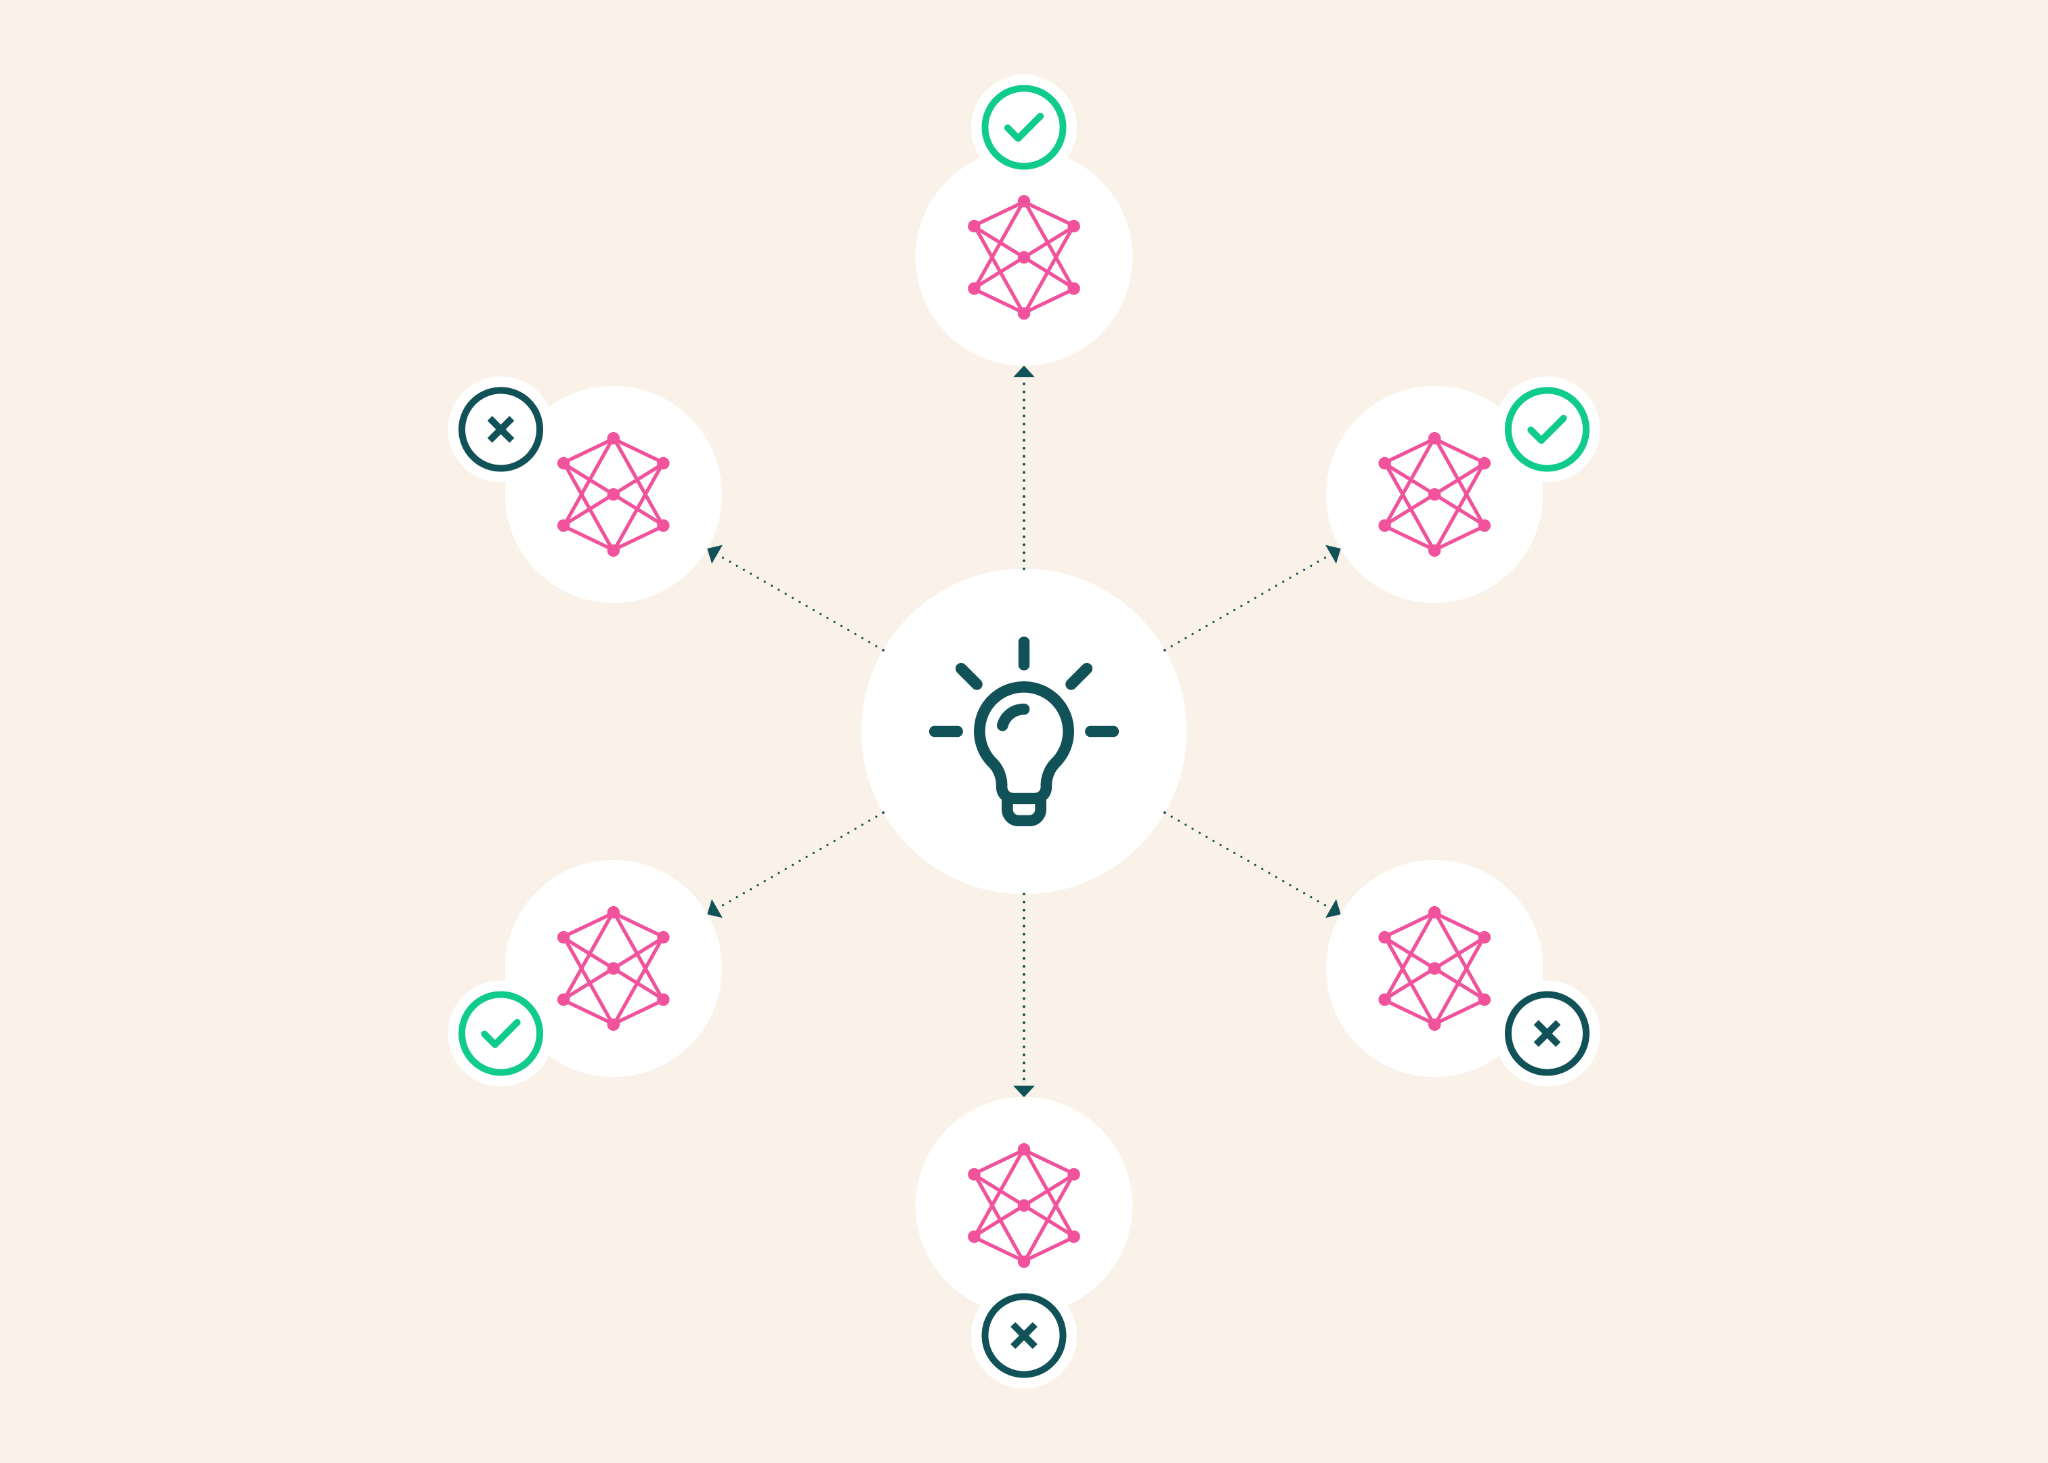
Ai2 has released Old Ideas, Novel Problems, a study of how reliably large language models can judge whether a research idea is novel, along with a benchmark, data, and code for testing novelty judges and an automated pipeline for building new evaluation sets. The work supports Ai2‘s broader effort to automate parts of scientific discovery with systems like DataVoyager, AutoDiscovery, and Theorizer; generating a plausible idea is only half the problem, since researchers also need to know whether it is genuinely new. In practice that judgment is often delegated to another LLM, a novelty judge, and there is no standard way to build one: teams choose a model, prompt, evaluation format, reasoning budget, and sometimes a literature-retrieval system, and those choices can materially change the verdict.
To measure the reliability of such judges, the researchers built an automated pipeline around ICLR 2026 peer reviews. Instead of treating acceptance as a proxy for novelty, they mined review text for passages where reviewers explicitly discussed a contribution’s originality, since an accepted paper can lack novelty and a rejected paper can still be original. The high-novelty pool contains 154 human-authored ideas from accepted papers in the top-rated 10% of their ICLR research area whose reviewers positively identified novelty with no dispute; the lower-novelty pool holds 145 ideas from rejected papers in the bottom 10% whose reviewers raised originality concerns without any positive novelty signal. In a check of the mining process, an annotator agreed with the extracted novelty-signal polarity in 47 of 50 cases. These pools form the Human-Only setting. A second Human+Generated setting pairs the same 154 validated human ideas with 154 ideas from a simple LLM generator that received only a research area and an instruction to propose a novel idea; the generated ideas are treated as weak labels for lower novelty, not verified judgments. An expert review of 30 pairs, weighted toward cases the strongest judge got wrong, preferred the human idea in all 30 and judged none of the generated ideas novel. The authors also rewrote the human- and AI-generated ideas into a common structure to check whether judges were reacting to writing style rather than substance, and they note that many core findings do not depend on the labels at all: if two reasonable setups give opposite answers for the same pair, that disagreement itself shows instability.
Across six LLM judges — GPT-5.1, GPT-5.2, GPT-5.4, Claude Sonnet 4.5, Claude Opus 4.5, and Claude Opus 4.6 — small changes in setup produced dramatically different verdicts, with prompt changes causing the largest shifts. GPT-5.4 on the Human+Generated pairs scored 93.5% accuracy when told that reviewers had found exactly one novel idea per pair, but dropped to 40.9%, below chance, with a simpler prompt that merely asked which idea was novel, changing its verdict on more than half of the same pairs. The same prompt change shifted Human-Only accuracy by only about seven percentage points, and by 21 points for Claude Opus 4.6, suggesting a judge can look stable on human-authored ideas yet behave very differently on AI-generated ones. There was no universally better prompt: for example, dropping an instruction that warned against treating trivial or incremental contributions as novel improved accuracy for some judges and reduced it for others. In comparisons between ideas from two AI generators, roughly a quarter to a third of verdicts changed on average across the six judges under different prompts.
More search and reasoning did not reliably help either. GPT-5.6 Sol with an extra-high reasoning budget and live iterative search restricted to arXiv scored 0.78 macro-F1 on Human+Generated, 11 points behind Claude Opus 4.6 at 0.89, while costing roughly 10 times more per decision. Purpose-built evaluators also underperformed a simple baseline: a prompted Claude Opus 4.6 with low reasoning and majority voting across three calls scored 0.854 macro-F1 at a total cost of $2.59, while Idea Novelty Checker scored 0.642 at $30.66 and Sakana AI’s AI Scientist scored 0.772 at $82.05. The authors conclude that LLM-based novelty evaluation remains a major open problem and is especially brittle on the AI-generated ideas these systems are increasingly asked to judge. They recommend testing judges on the kinds of ideas they will actually evaluate, measuring sensitivity across prompts and models, improving how prior literature is incorporated, and building benchmarks that can evolve as the literature grows. The released benchmark and reusable pipeline are intended to let researchers apply the approach to new peer reviews, other scientific communities, and future generations of novelty judges.