LFM2.5-VL-DSpark: Speculative Decoding for VLMs
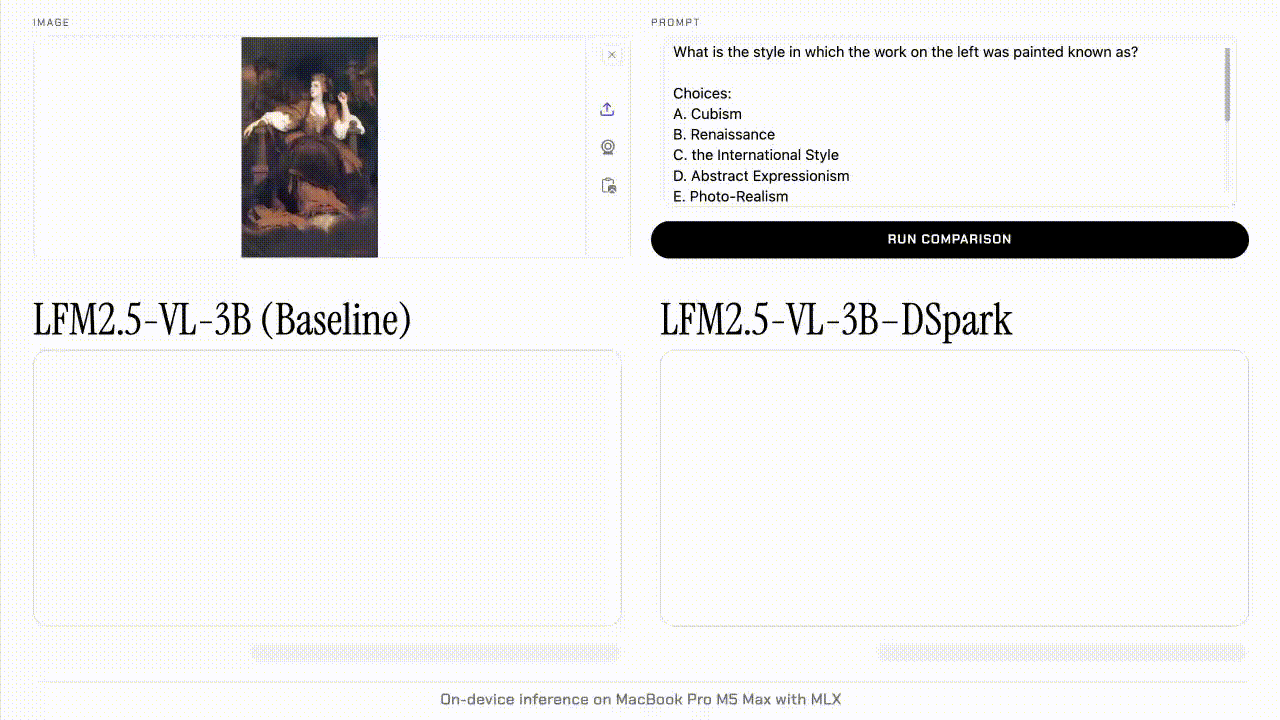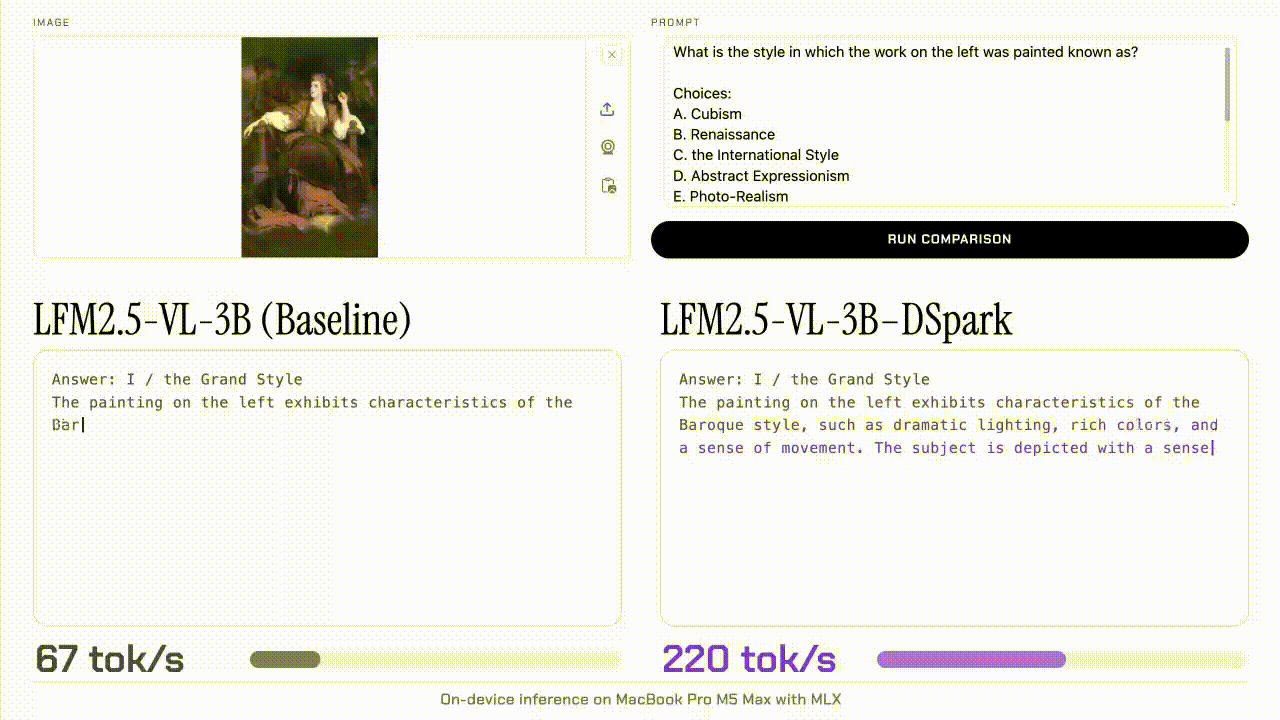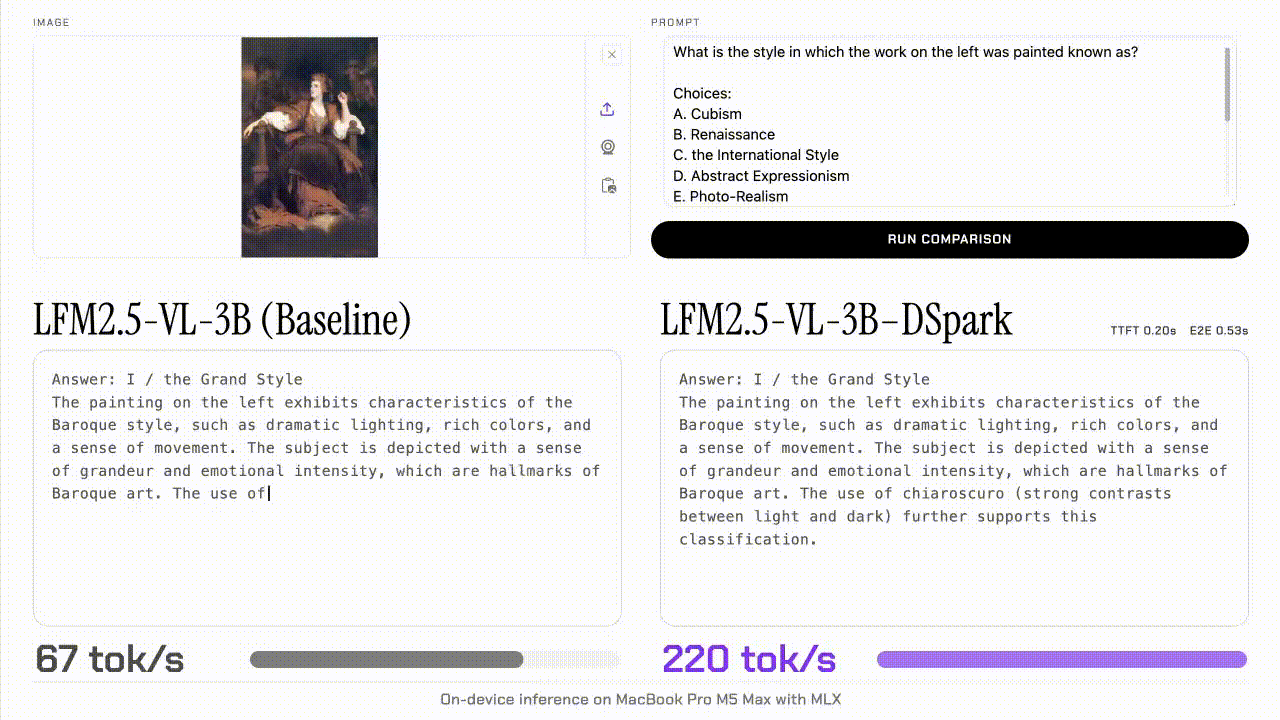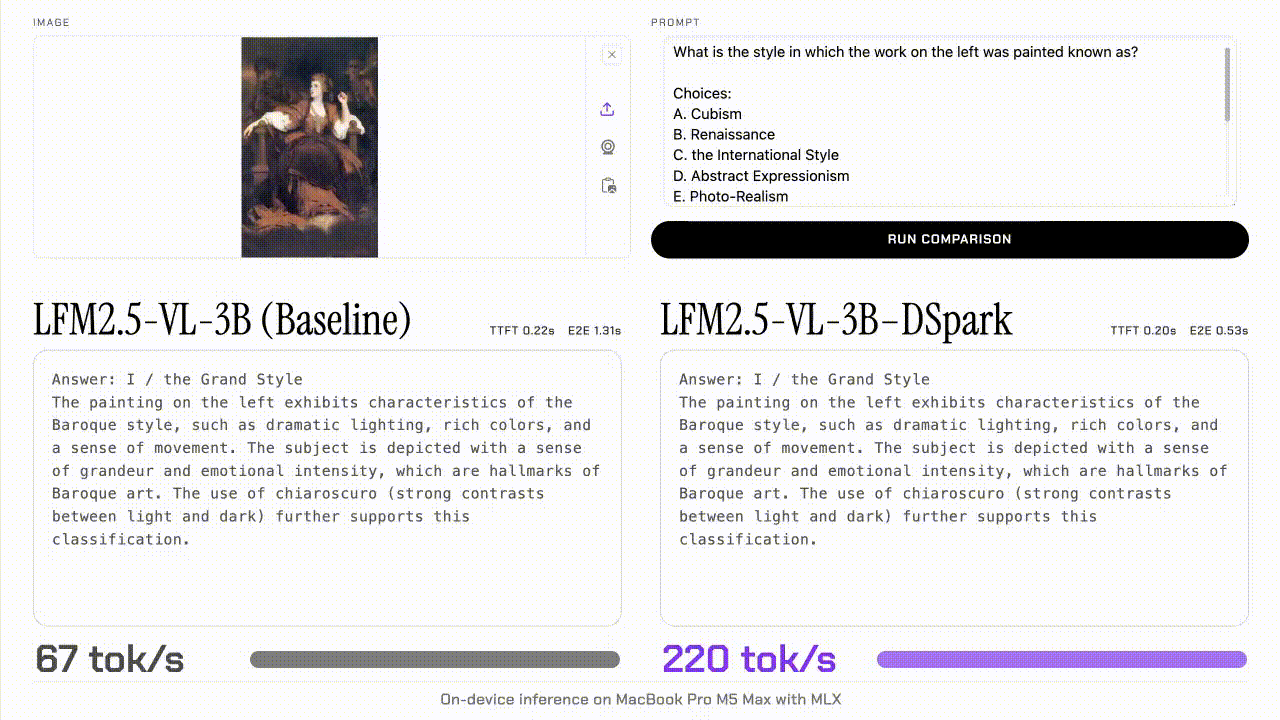
Liquid AI released an experimental DSpark draft model for the vision-language model LFM2.5-VL-3B. Like the earlier LFM2.5-DSpark text drafters, it adds a speculative decoding path that trades a small memory increase for a larger speedup while preserving output quality. The drafter adds 280M parameters, or 8.9% on top of the 3B target, and ships with day-one integrations for llama.cpp, MLX-VLM, and SGLang. Measured decode speedups reach 3.13x on device and 2.66x on an H100, with end-to-end gains up to 2.62x and 2.27x respectively.
Speculative decoding for this VLM uses the same architecture as the text DSpark drafters. The drafter captures the target model’s hidden states at a fixed set of tapped layers and conditions on them to draft a block of k candidate tokens. Image patches and text tokens are projected into a shared representation before those layers, so the drafter sees hidden-state vectors of the same dimensionality regardless of modality; the inference algorithm is unchanged from the text models.
The model follows the DSpark recipe with a mixture of vision-language SFT data weighted toward expected workloads. Ablations across 3, 4, and 5 layers led to a simplified attention-only drafter with 4 layers and a block size of 9. The final mixture was trained for 10 epochs; acceptance improved with more tokens before hitting diminishing returns. At inference time the recommended block size is 8 or 9 depending on hardware. Parameter counts are 193.0M for the 4-layer decoder stack, 21.0M for the hidden-state projection, 65.5M for the Markov head, and 6.4k for norms and confidence head, totaling 279.5M.
Speedups were measured with block size 8 on six vision-based tasks—general VQA, text VQA, image captioning, chart VQA, complex reasoning, and multi-turn conversation—following the MMSpec benchmark. With MLX on an M5 Max, decoding ran 2.30x to 3.13x faster by task, and end-to-end latency improved 1.56x to 2.62x. On an M3 Ultra via llama.cpp, decoding improved 1.57x to 2.14x and end-to-end 1.30x to 1.77x. On an H100, decoding speedup peaked at 2.66x and end-to-end gains ranged from 1.64x to 2.27x.
The post also notes a key boundary: speculative decoding accelerates only the decode phase. In LLMs prefill is mostly compute-bound and grows (sub)quadratically with prompt length; VLMs add a vision encoder and hundreds of visual tokens that the language backbone processes. On edge devices prefill takes up more of end-to-end latency, as time-to-first-token and decode measurements on Apple silicon and H100 show, though the M5’s per-core GPU neural accelerators narrow that gap. The overall speedup is therefore capped by the portion of the workload not accelerated—Amdahl’s law.
Using the model with SGLang requires a build with DSpark support for LFM2 targets (PR #40651). The target is launched with the draft attached via the –speculative-* flags; block size is read from the draft’s config.json. The llama.cpp path needs PR #29339 and a command that passes the draft GGUF and sets –spec-type draft-dspark; MLX-VLM needs PR #2280 and reads block size from sidecar metadata. Speculative decoding is described as exact: the target verifies every proposed token, so greedy output matches the target alone, and per-response timings report draft_n / draft_n_accepted. Weights are available on Hugging Face in Safetensors and GGUF formats, and the post includes a citation for Liquid AI‘s Sep 2026 blog.