LFM2.5 Q4_0 Checkpoints from Quantization-Aware Distillation
Liquid AI has released Quantization-Aware Distillation (QAD) Q4_0 GGUFs for four LFM2.5 models: LFM2.5-230M, LFM2.5-350M, LFM2.5-1.2B-Instruct, and LFM2.5-2.6B.
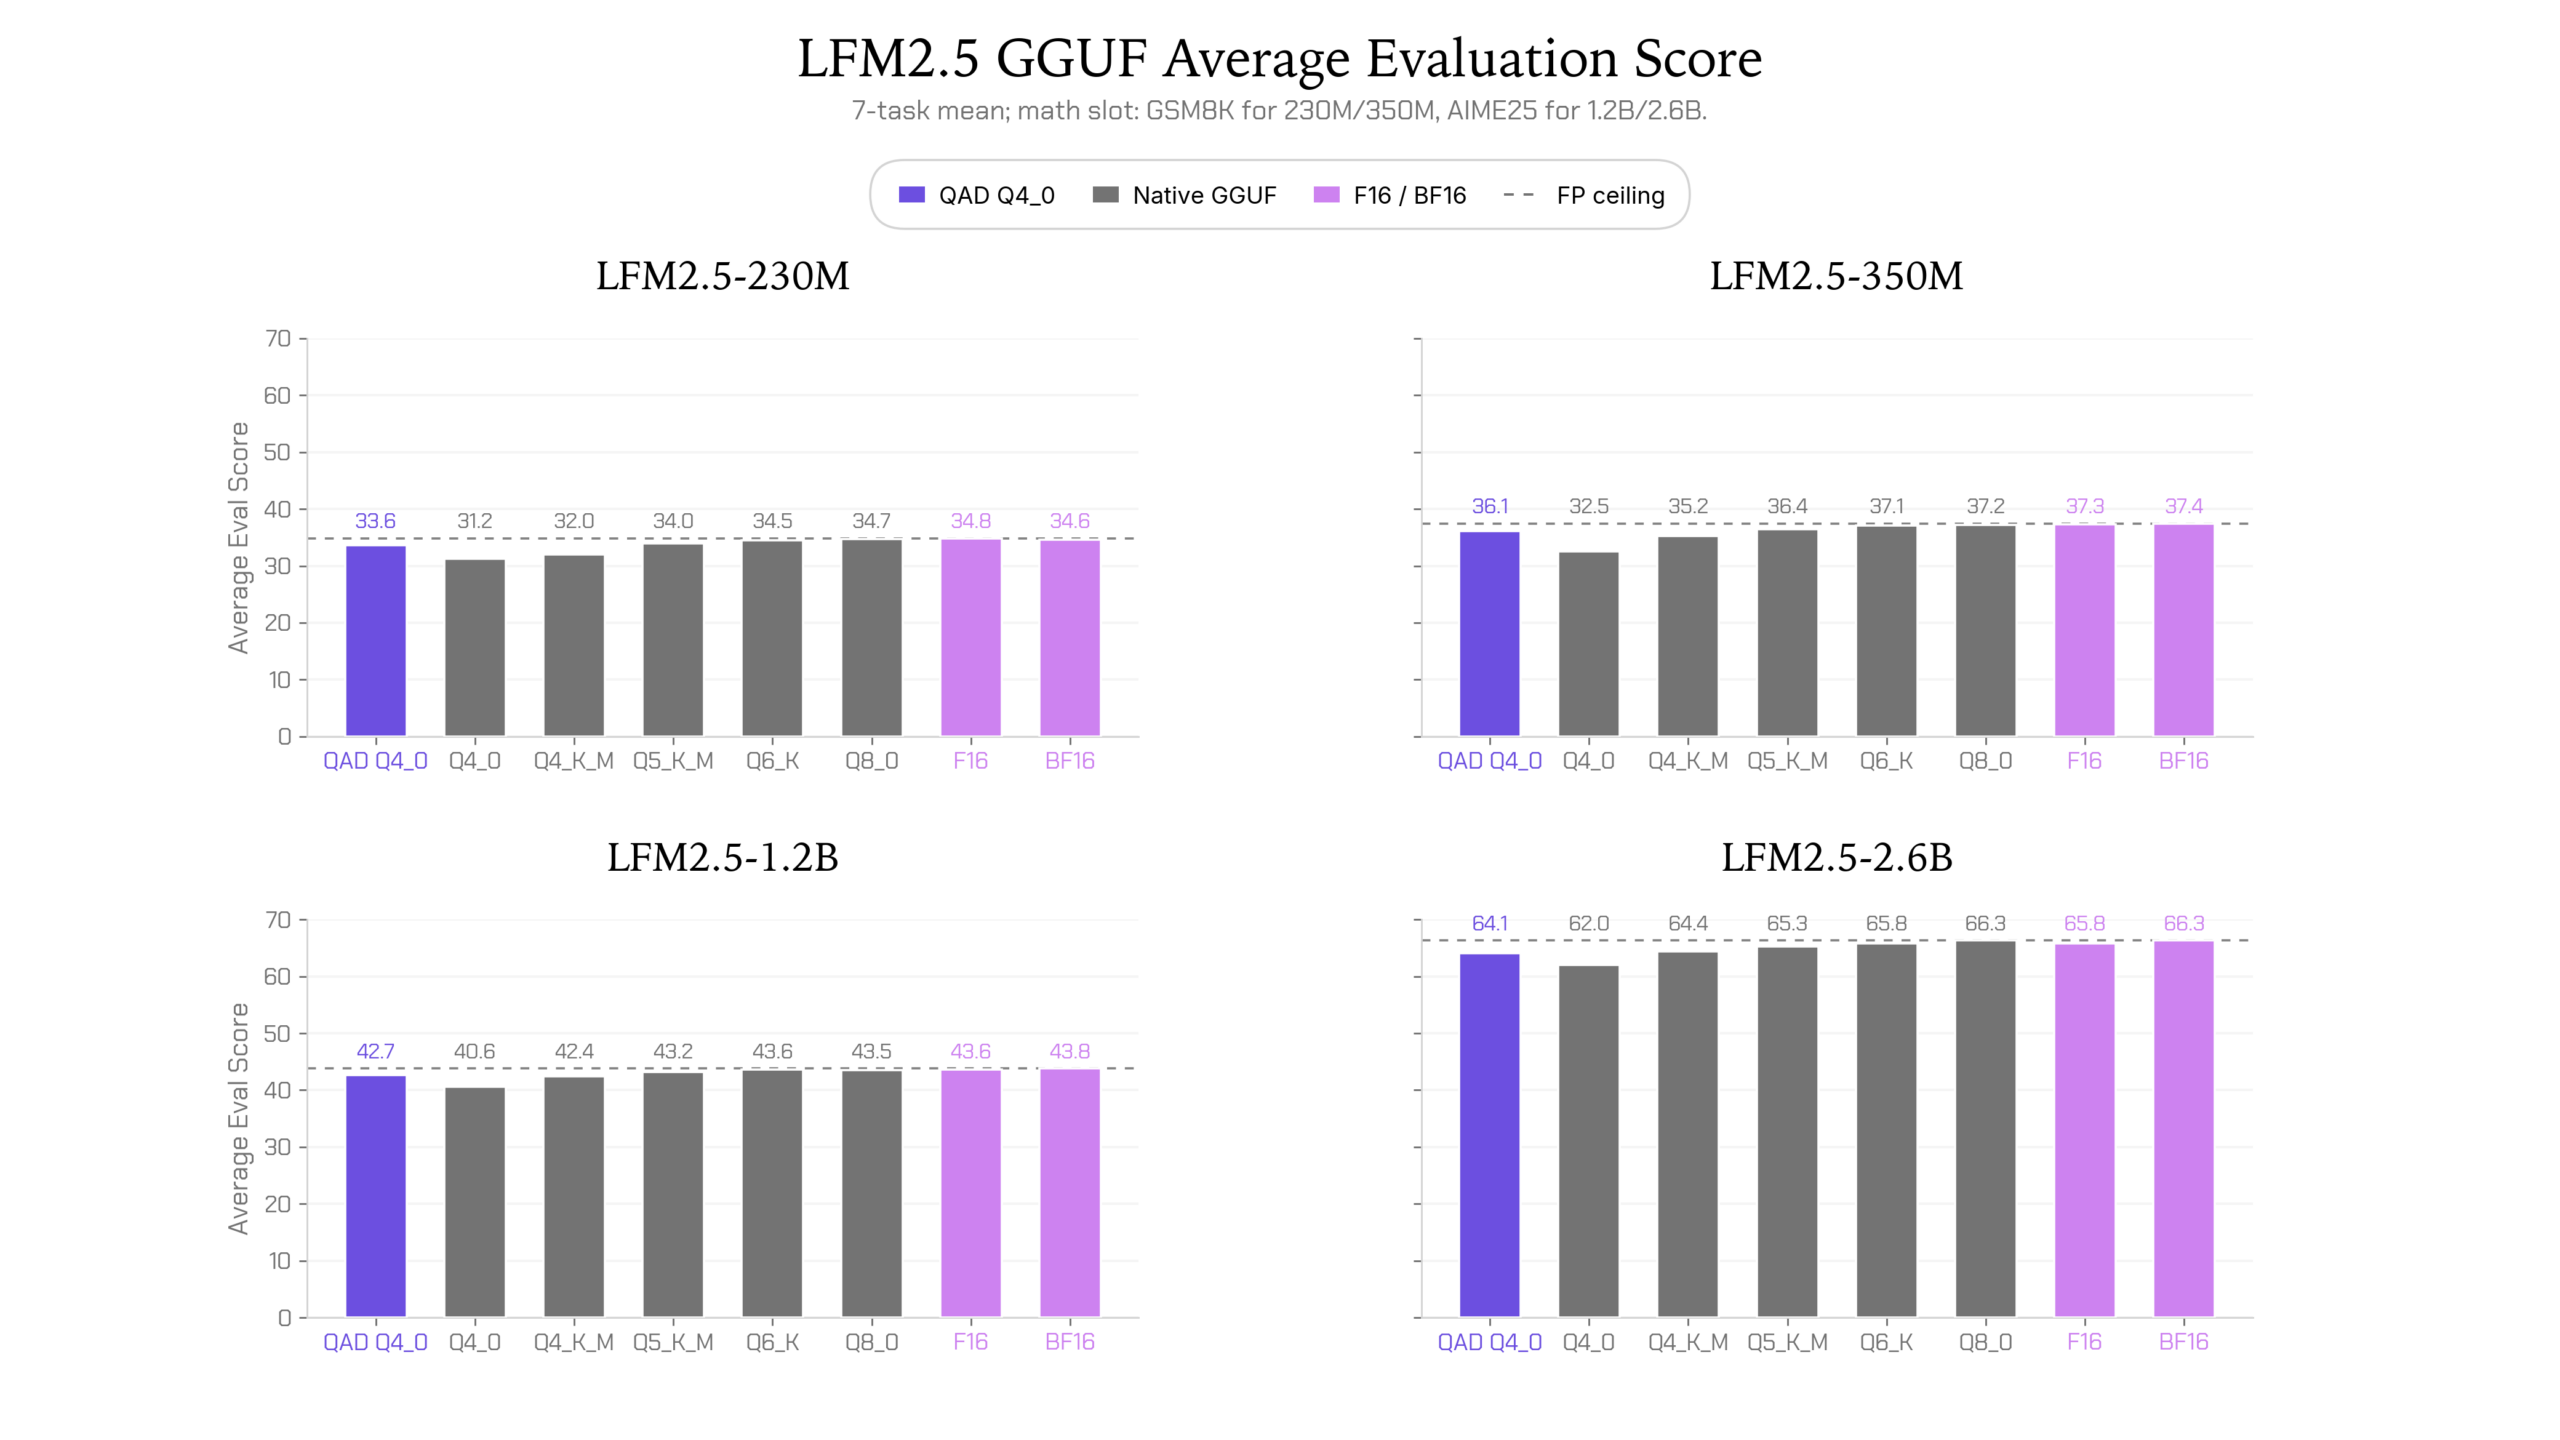
These checkpoints are designed to run at Q4_0 memory and speed while recovering most of the accuracy lost during quantization. For example, the QAD checkpoints retain 96.5–97.
4% of their respective BF16 baseline performance on a benchmark suite covering GPQA Diamond, MMLU-Pro, IFEval, IFBench, Multi-IF, and BFCLv4.
The BF16 GGUF is used as the in-format ceiling, with mean results across five repeats. The company also measured edge-hardware performance.
The 230M and 350M QAD Q4_0 checkpoints match Q5_K_M quality within evaluation variance at 4–33% higher decode throughput, while the 1.2B and 2.
6B versions match Q4_K_M quality at 3–14% higher throughput. They also match Unsloth’s UD-Q4_K_XL. Developers can use the files with llama.cpp or any runtime that supports GGUF Q4_0 artifacts.
The QAD GGUFs are available on Hugging Face for all four model sizes.