Most AI Work Can Wait
Most teams building AI agents start by picking a model, then design the architecture. That order is backwards. The model choice should be the last decision, not the first. The critical component is the router—a small piece of code that decides which tier of model handles each request. Getting the router right means 70–80% of traffic runs on local models (costing nothing per call) or on async models that reduce AI spend by 90%+. Brian Armstrong recently made a similar point about Coinbase cutting AI spend in half while token usage grew, achieved through better defaults, routing, and caching rather than friction and spend alerts.
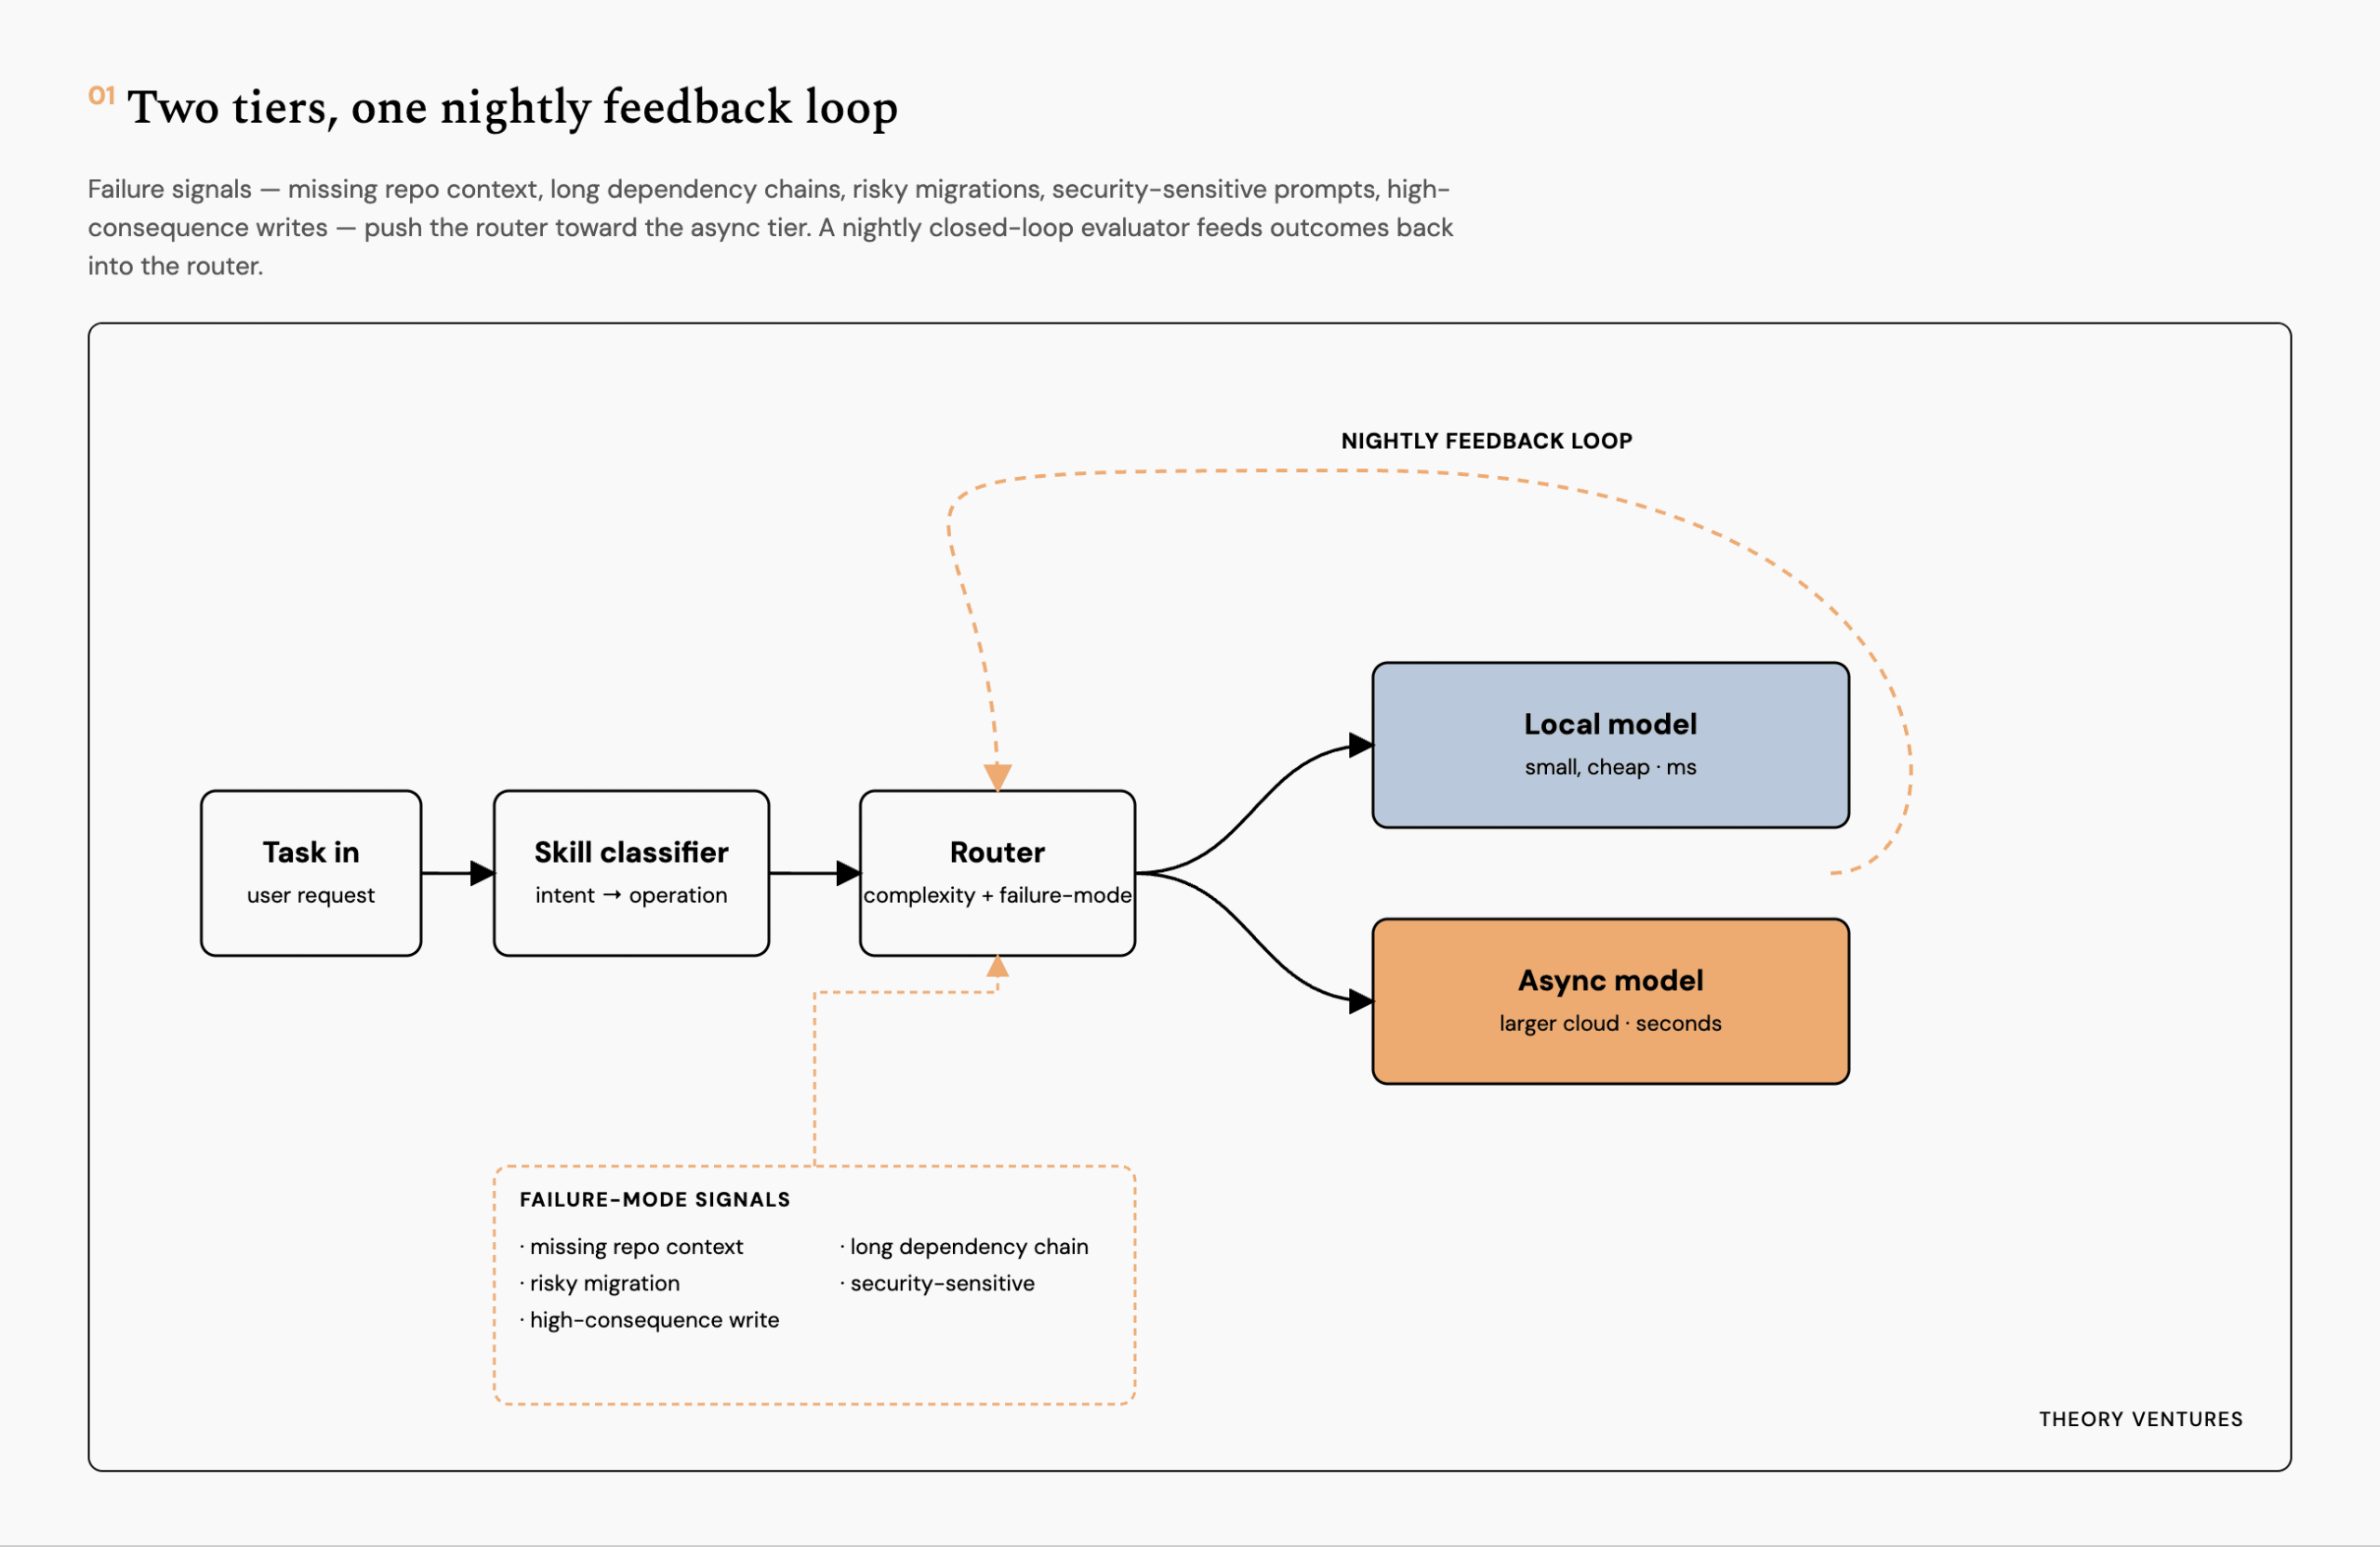
The routing problem decomposes into three layers, each with a distinct job. The skill classifier turns a raw user request into a concrete operation—intent recognition like “draft a reply” or “summarize a repo.” The router decides which tier (e.g., local, async, real-time) executes the classified operation; it reads only the classifier’s label plus a few features like complexity, context size, and historical success rate, not the raw prompt. The model selector picks the cheapest model within a tier that meets a confidence threshold. Conflating classifier and router buries the model choice inside the prompt and prevents A/B testing different models against the same operation.
Local compute is nearly free, and async batch reasoning runs two orders of magnitude cheaper than real-time inference. The real question is how much work needs real-time answers. Surprisingly little, once the system can queue work. A draft reply, repo summary, diligence memo, or nightly evaluator run does not need to return in a second. The author built a first version of this into an agent runtime, with the router already scoring tasks on complexity, context size, and local memory retrieval. Two feedback mechanisms sit on top of the router, operating on different time scales. A synchronous predictor annotates each incoming route with five features: missing repo context, long dependency chains, risky migrations, security-sensitive prompts, and high-consequence writes. A nightly closed-loop evaluator scores yesterday’s traces overnight and updates the router’s weights, running on async inference to keep evaluation cost near zero. The synchronous predictor catches known-hard tasks before they fail; the nightly loop discovers new failure modes the predictor missed.
Once skill distillation flattens the operation set, 70–80% of agent traffic can run on local models for most non-coding work. The implication is clear: design your system around routing, not around models. Pick your models last.