OpenAI’s Jalapeño chip shows strong inference benchmark results
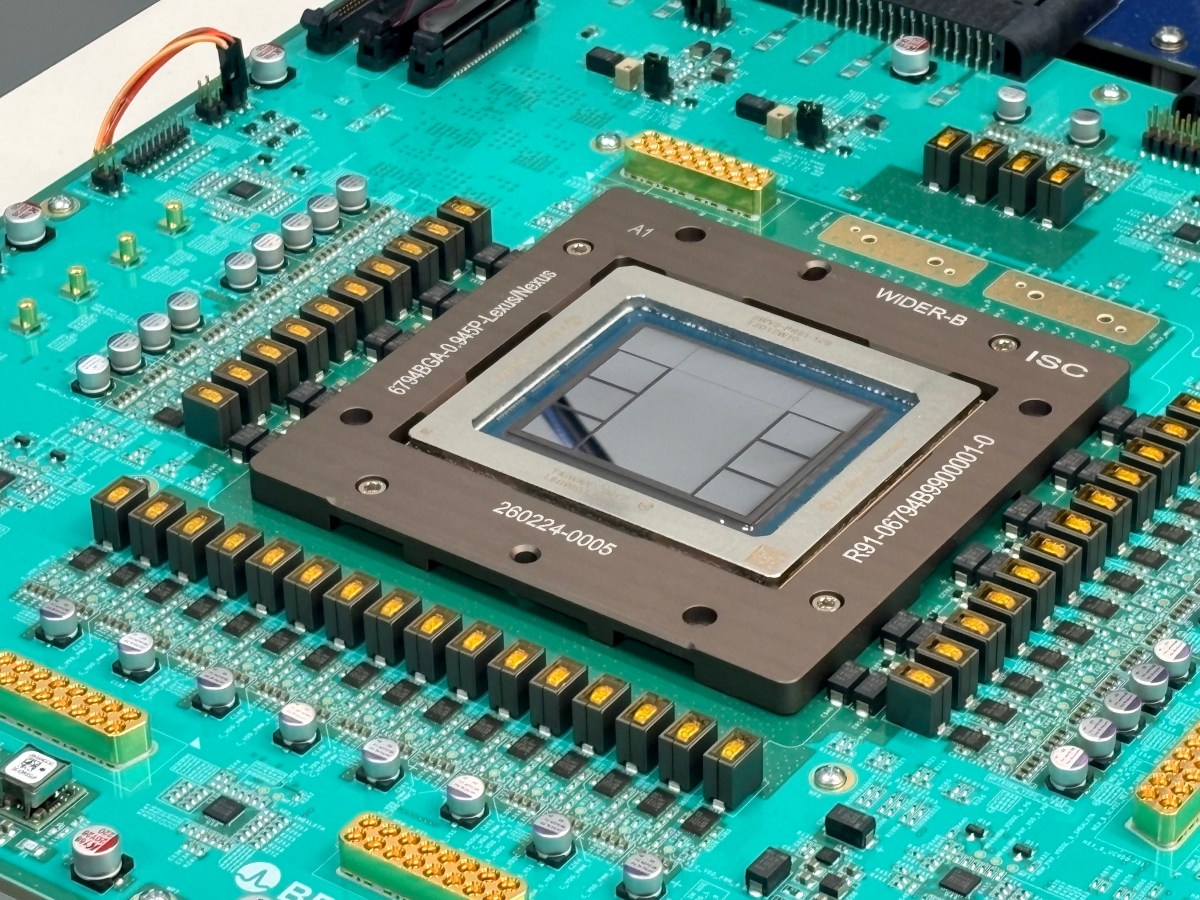
At the Hot Chips conference on Tuesday, OpenAI released the first benchmark results for its Jalapeño inference chip, developed with Broadcom. Tested on SemiAnalysis’ InferenceX benchmark, Jalapeño delivered more tokens per user and more throughput per kilowatt than current state-of-the-art inference processors, with OpenAI‘s head of hardware Richard Ho calling the advance “very, very significant.” The comparison was made against an Nvidia Blackwell system, but Ho noted the competitive landscape could shift by the time Jalapeño reaches full deployment, which he estimated at the end of 2026 in very small volumes and more significantly in 2027.
First announced last October, Jalapeño was developed with OpenAI‘s own models assisting in the process. The company plans to make it a multigenerational platform, co-designing AI products, models, chips, and memory together. This full-stack approach let OpenAI address specific bottlenecks in the inference pipeline, particularly the prefill and communication phases. According to the company’s blog post, Jalapeño minimizes data movement and communication delays by keeping model state—including the KV cache—explicitly placed and local, activating the right combination of compute, memory, and networking for each inference phase.