Granite Timeseries Ensemble: Four Open Models, One Forecasting Recipe
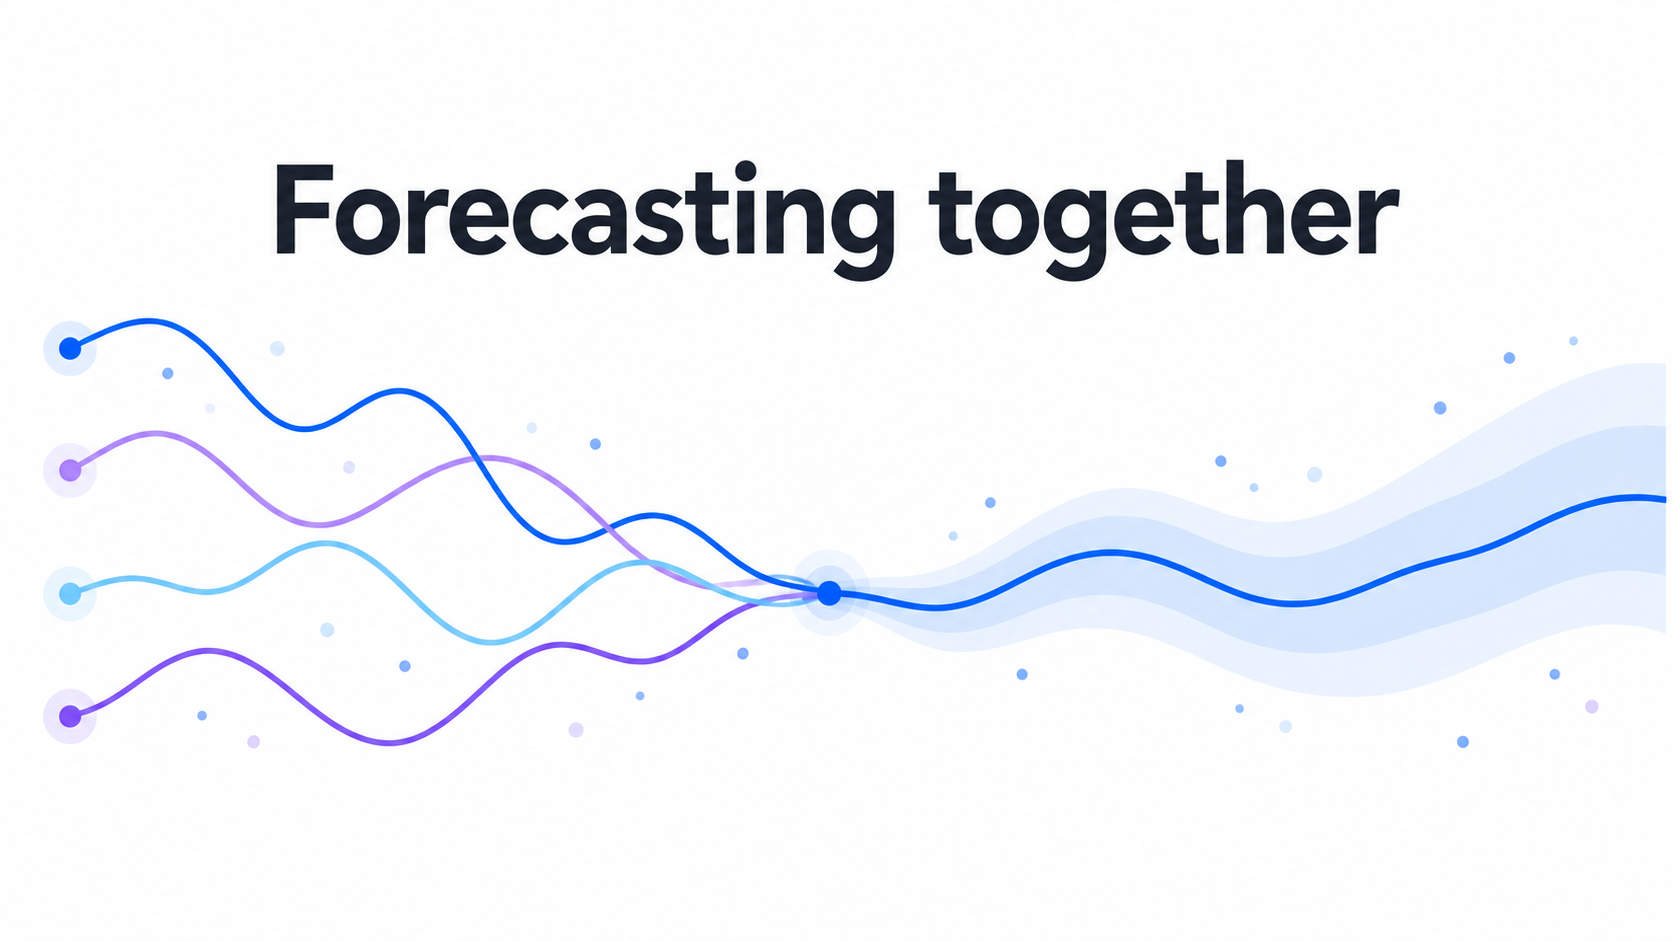
Granite Timeseries Ensemble is a single forecasting interface in Granite TSFM that combines four pre-trained Granite time-series models into one recipe. It returns a point forecast from the ensemble median and quantile predictions ranging from 0.1 to 0.9, with no retraining and no fitted ensemble weights. The recipe stores configuration rather than merged model weights, and member checkpoints are downloaded at runtime. Developers load it with QuantileEnsembleForecaster.from_pretrained(“ibm-granite/granite-timeseries-ensemble-r1”), then call the forecaster with a DataFrame, timestamp column, target column, context length, and prediction length. The default recipe and its Granite members are permissively licensed.
Two aggregation methods are included. The Probabilistic Ensemble is the recommended default: it gives each member equal influence, pools their quantile forecasts in probability space, and extracts the requested quantiles, so there are no weighting hyperparameters to tune. The IQR Ensemble is an adaptive alternative: it weights members by forecast spread, giving narrower intervals greater influence, with weights varying by sample, target, and horizon step, and isotonic regression preventing quantile crossing. The article cautions that a narrower interval does not necessarily mean a better-calibrated forecast, and IQR weighting can favor an overconfident member; temperature and per-member weight caps are available for experimentation. The default members are PatchTST-FM-r1, PatchTST-FM-r2, FlowState-r1.1, and TTM-r3, which capture trends, seasonality, and local variation in different ways so their errors need not coincide.
Both recipes were evaluated on 97 GIFT-Eval configurations with no fine-tuning and no use of test targets to select or fit the aggregation method. On aggregate MASE and average MASE rank, both ensembles outperformed all four individual members: the Probabilistic Ensemble achieved the lowest MASE among the six forecasts shown (0.683 versus 0.685 for PatchTST-FM-r2). PatchTST-FM-r2 retained the lowest aggregate CRPS/MWQL score (0.467), while the IQR Ensemble achieved the lowest average CRPS rank among the six. Aggregate error and average rank therefore favor different choices. The article stresses that the MASE margin over the best single member is small, so the main benefit is robustness: comparable or better aggregate accuracy without knowing in advance which architecture will suit the data. In the 20 October 2026 leaderboard snapshot, the ensemble approach ranked third among eligible systems on both MASE rank and CRPS rank; some excluded systems, such as fine-tuned or non-permissively licensed entries, scored better.
The common Forecaster interface also accepts compatible external models, so developers can change the member mix or aggregation method while keeping the same downstream forecast format, with no merging or retraining of member checkpoints. Expanded recipes that add IBM Research checkpoints carry separate license terms, including non-commercial and research-use restrictions, so each member’s model card should be reviewed before use. For new combinations, the article recommends checking forecast compatibility, accuracy, calibration, latency, and licensing.
Stated limitations: the current recipe forecasts multivariate channels independently without using cross-channel information, loading four checkpoints increases inference time and memory relative to a single member, and member context limits, horizons, preprocessing, and missing-value handling differ. Neither aggregation method guarantees calibration or robustness under distribution shift, so the article recommends backtesting on representative data, comparing the Probabilistic Ensemble, IQR Ensemble, and a strong individual member such as PatchTST-FM-r2, checking quantile loss and empirical coverage alongside MASE, and measuring runtime and memory cost.