Fine-Tuning Nemotron for Gold-Level IOI and IMO Results
The International Olympiad in Informatics (IOI) and the International Mathematical Olympiad (IMO) test very different skills: IOI requires algorithms and code that pass hidden tests under strict time and submission limits, while IMO demands rigorous natural-language proofs. The reported results show that the Nemotron model family can be adapted to both, reaching gold-medal level at IMO 2026 and IOI 2026 without building a new foundation model for each competition.
The specialization recipe had four parts: start with a strong Nemotron base model, curate domain-specific problems and high-quality reasoning traces, apply standard post-training methods such as supervised fine-tuning (SFT) and reinforcement learning (RL), and pair the specialist model with an inference loop that generates, evaluates, and improves candidate answers. The authors emphasize that fine-tuning should mean more than making a checkpoint trainable; it should mean a capable foundation model can be adapted to a demanding domain with a clear, reusable recipe.
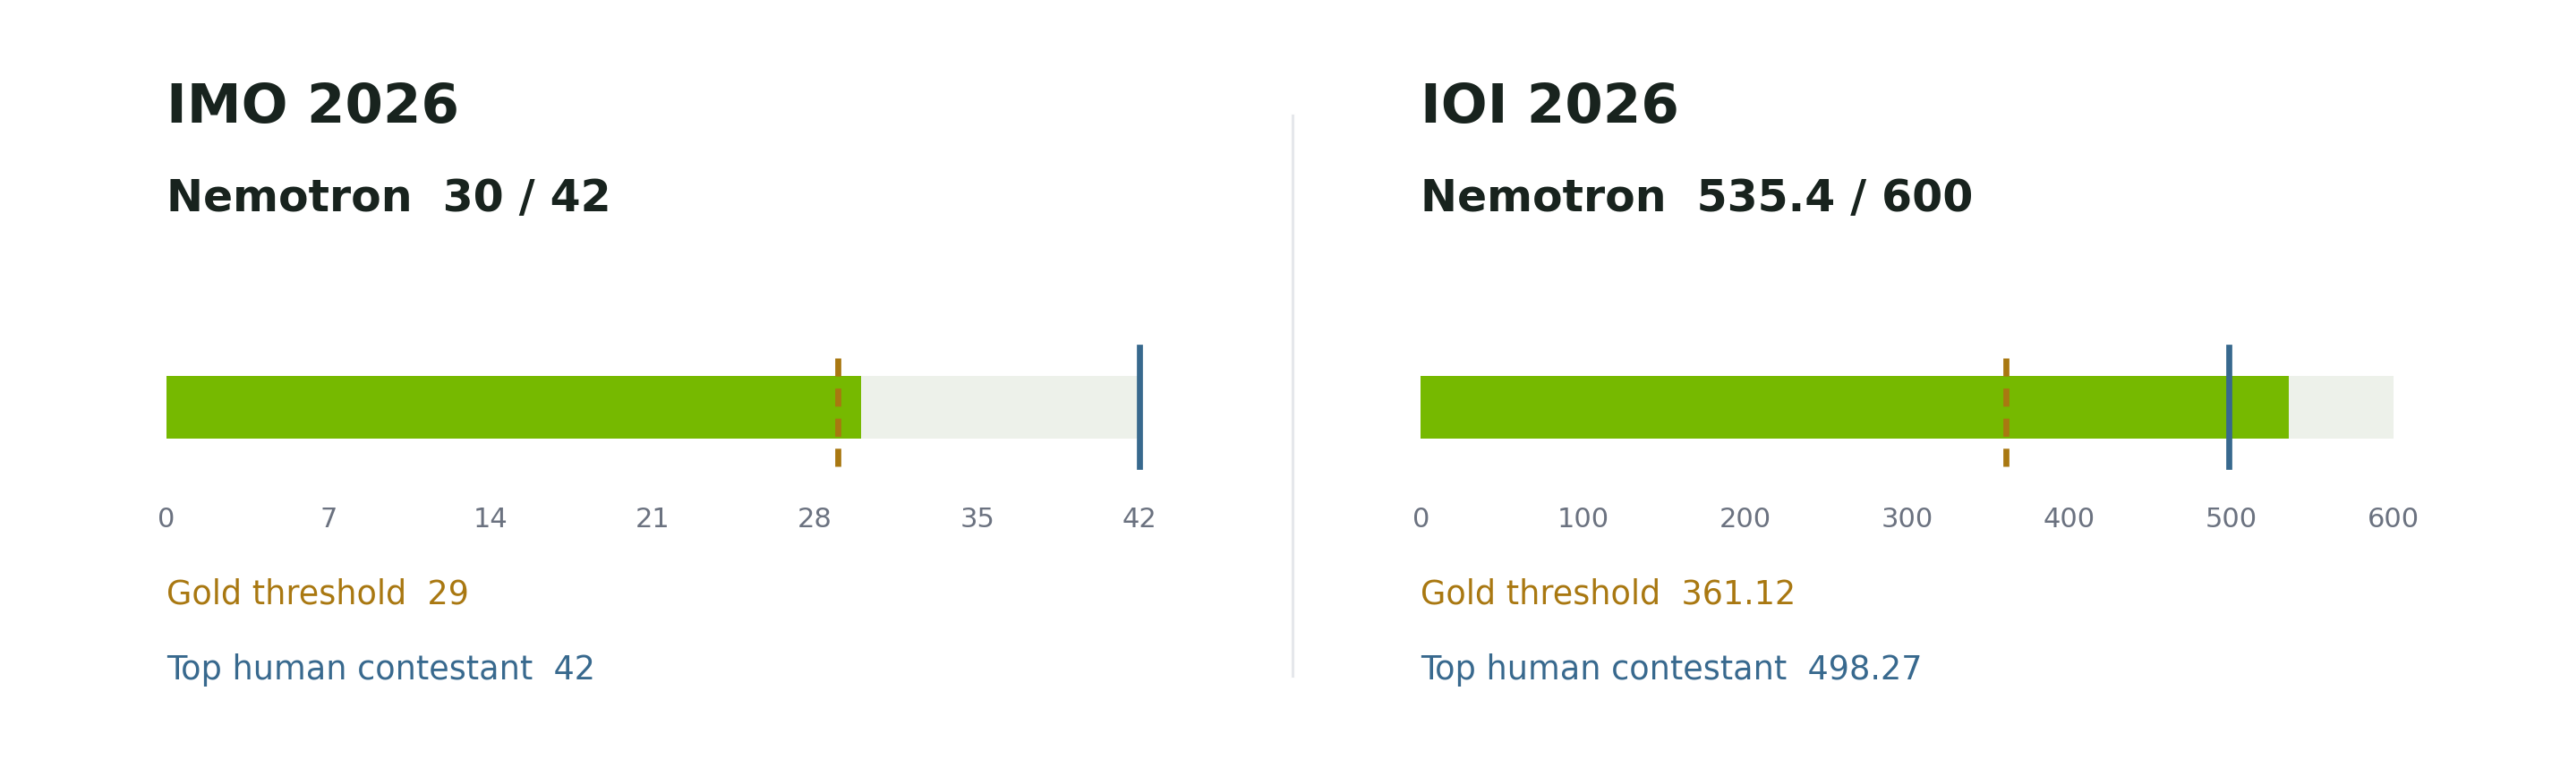
For competitive programming, the teams curated 22,000 problems and generated synthetic reasoning traces to train two specialists. Nemotron-3-Nano-CC, with 30 billion total parameters and 3 billion active parameters, received both SFT and RL. Nemotron-3-Ultra-CC, with 550 billion total parameters and 55 billion active parameters, received SFT. On the IOI 2025 benchmark, Nano improved from 130 points before post-training to 280 after SFT and 291 after RL. With GenCorrect, an iterative generate-evaluate-refine strategy, it reached 468 points, crossing the gold threshold of 438.3. Ultra-CC reached 502 points with the same test-time strategy. The experiments also showed that adaptation looks different at different scales: SFT produced most of Nano’s gain, with RL adding a smaller but consistent improvement, while for the stronger Ultra model, one SFT epoch was enough to outperform the fully post-trained Nano model across IOI, ICPC, and LiveCodeBench Pro. The competition-specific Ultra-CC system used for IOI 2026 scored 535.4 out of 600, above the 361.12 gold threshold and the top human score of 498.27. That IOI result came from a live, prospective run under the same time, internet-access, and submission constraints as human contestants, though it was an unofficial, unsupervised benchmark and was not included in the official IOI ranking.
The IMO project applied the same idea to olympiad mathematics, starting from Nemotron 3 Ultra. The SFT corpus contained 414,890 quality-filtered examples across 15,818 unique proof problems, covering proof generation, refinement, verification, and meta-verification so the model learned to construct arguments, identify gaps, respond to critiques, and judge whether a proof was complete. The RL model was trained on 9,597 proof problems selected near the model’s capability frontier. Both post-trained checkpoints outperformed the general-availability model in development experiments. The SFT checkpoint was strongest in the first search round, while the RL checkpoint achieved the best overall single-checkpoint result. Because their strengths were complementary, the final system used both specialists alongside the general model. For each IMO problem, the models generated candidate proofs, scored them, produced critiques, and refined the most promising attempts, with a separate high-compute stage selecting the final submission. The entire system worked in natural language, with no formal prover, external tools, or internet access. It scored 30 out of 42 points, including full credit on four of the six problems, exceeding the official gold-medal threshold of 29. The submitted proofs were graded by official IMO graders.
The combined conclusion is that fine-tuning and test-time compute work together. At IOI, GenCorrect turned gains from fine-tuning into larger improvements over multiple feedback rounds. At IMO, using complementary SFT and RL checkpoints was more valuable than simply drawing more samples from one checkpoint. The medals were not produced by fine-tuning alone, and they were not produced by brute-force sampling alone; they came from co-designing the model, the data, and the inference loop.
To make the results reusable, the Nemotron Labs IMO 2026 collection includes the SFT and RL checkpoints, both training datasets, and Nemotron-IMO-Bench, a new benchmark of 200 olympiad-level problems. The IMO paper describes the training approach and generate-verify-refine system, while the NeMo-Skills repository contains the IMO inference pipeline, prompts, submitted proofs, and a reproducible quickstart. For competitive programming, the Nemotron-3-Ultra-CC model is available on Hugging Face, and the IOI paper provides the training recipe and GenCorrect methodology. The IOI evaluation and inference pipeline are also available in NeMo-Skills.