Same Model, Different Harness: CUGA vs Hermes vs Deep Agents on AppWorld
Community lists like awesome-agent-harness and best-of-Agent-Harnesses track nearly 200 agent harnesses, and an analysis cited by best-of-Agent-Harnesses shows the same GLM-5.2 model going from 23% to 52% on SWE-bench Pro when only the harness changed. The article reports a controlled comparison by the CUGA team: same open-weight model, three harnesses, 90 AppWorld tasks. Hermes (Nous Research) is built for always-on personal assistants, and Deep Agents (LangChain) for long multi-step research-style tasks; CUGA (ConfigUrable Generalist Agent) is IBM’s open-source harness for enterprise automation.
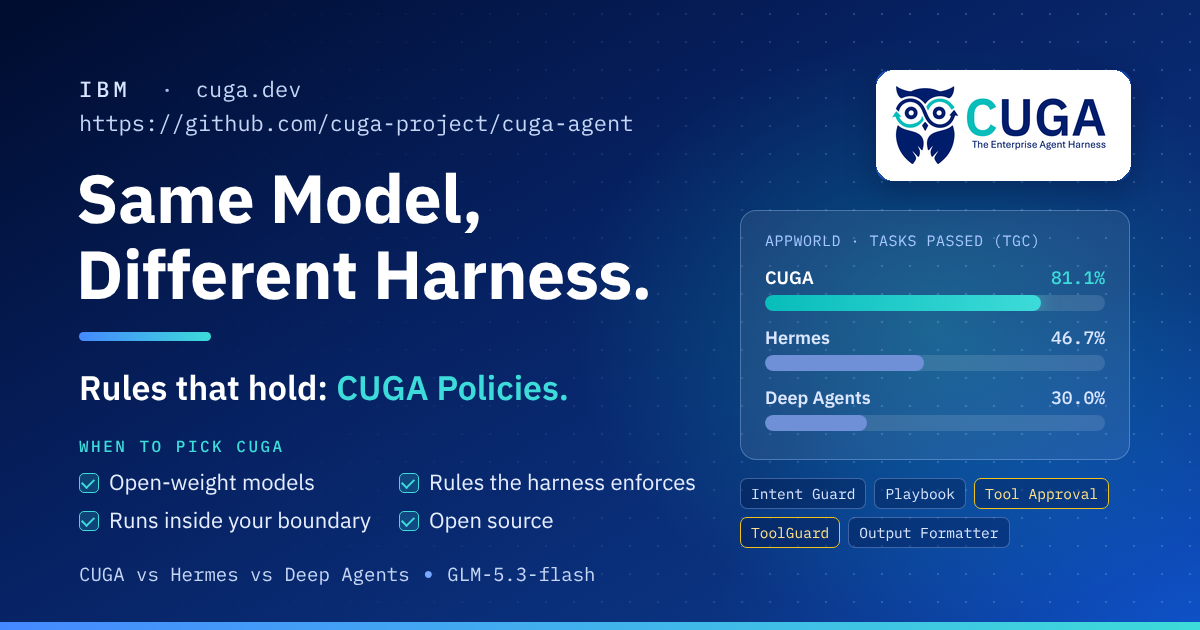
The experiment kept the model fixed and changed only the harness. Every run used GLM-5.3-flash on the same 90 tasks in 30 scenarios, with one attempt per task, under the Harbor evaluation framework; the setup is public in the harbor-eval fork. AppWorld is a benchmark of multi-step tasks across 9 apps and 457 APIs (email, payments, file storage), a proxy for a subset of enterprise automation capabilities. Results: CUGA passed 73/90 tasks (81.1% TGC) and 20/30 scenarios (66.7% SGC); Hermes passed 42/90 (46.7%) and 8/30 (26.7%); Deep Agents passed 27/90 (30.0%) and 2/30 (6.7%). The authors stress this is not a verdict on Hermes or Deep Agents—neither was built for multi-app API work—and that SGC is the more meaningful number because a scenario passes only when all three variants pass, rewarding consistency. Three stated limits: the 90-task sample may not generalize, the setups were not identical (CUGA used an AppWorld configuration the others did not), and the runs did not use policies, so policy enforcement is not measured.
CUGA‘s points come from the harness loop: prepare, call the model, execute, repeat, scaling from a single CugaAgent to a CugaSupervisor coordinating agents locally or over A2A. Features in the AppWorld setup include task decomposition into per-app steps, focused tools that show each step only its app’s tools plus a few shared ones, a tool shortlister (find_tools), CodeAct (model writes Python that calls APIs), a sandbox with time limits, verification before execution, automatic reflection, and a pagination audit that flags full-page list calls when the next page was never requested. Net effect: the model makes fewer decisions, and the harness catches more mistakes before they reach the result.
The policy layer is what AppWorld does not test. Business rules in the system prompt are instructions, not enforcement: a model can misread them, a user can talk the agent out of them, or an injected message can change them mid-task. The authors describe this layer in the ACM CAIS 2026 paper Governance by Construction for Generalist Agents (arXiv). CUGA policies act at four points in every run: user intent (Intent Guard blocks or answers matching requests before the agent acts), agent guidance (Playbook gives the agent a standard procedure), tool execution (Tool Approval pauses for human approval and shows proposed code; Tool Guide with ToolGuard runs guard code before the tool and blocks the call with a policy violation), and final response (Output Formatter shapes the answer to an approved template). Guidance steers the model, but approvals and ToolGuards are enforced by the runtime, so rules like payment approval and PII handling belong in the enforced group. The Policy Playground demonstrates the difference: without policies, ‘Pay everything I owe.’ paid $90, including a denied claim in collections; with policies, the run held the payment for approval and paid only the $10 due.
Why pick CUGA: strong results with open-weight models now, hosted models at #1 on WebArena (February–September 2025) and AppWorld (July 2025–February 2026), runtime-enforced rules, deployment inside your sovereign boundary (Apache 2.0, any OpenAI-compatible endpoint, local or Kubernetes, air-gapped sovereign clusters, OIDC sign-in, separate chat and management roles), measurable cost via budgets and run receipts for tokens/tool calls/time, and configuration via UI/SDK instead of code. IBM Sovereign Core builds on CUGA to run agents entirely inside the customer’s boundary. When to pick something else: terminal coding agents—opencode, Codex, or Claude Code; personal always-on assistants—OpenClaw or Hermes; blank-canvas graph framework—LangGraph directly (CUGA is built on it). CUGA targets automating business work across APIs, apps, and web UIs under enforceable rules. The CUGA team invites configurations to harbor-eval if readers can make Hermes or Deep Agents do better; they will rerun on the same tasks and publish whichever wins.